Uploaded September 2026 | Updated November 2026, 3 days ago
Large language models demand significant computational power for inference, and TPUs are becoming a first-class target for serving them.
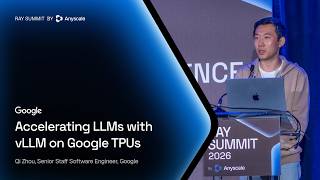
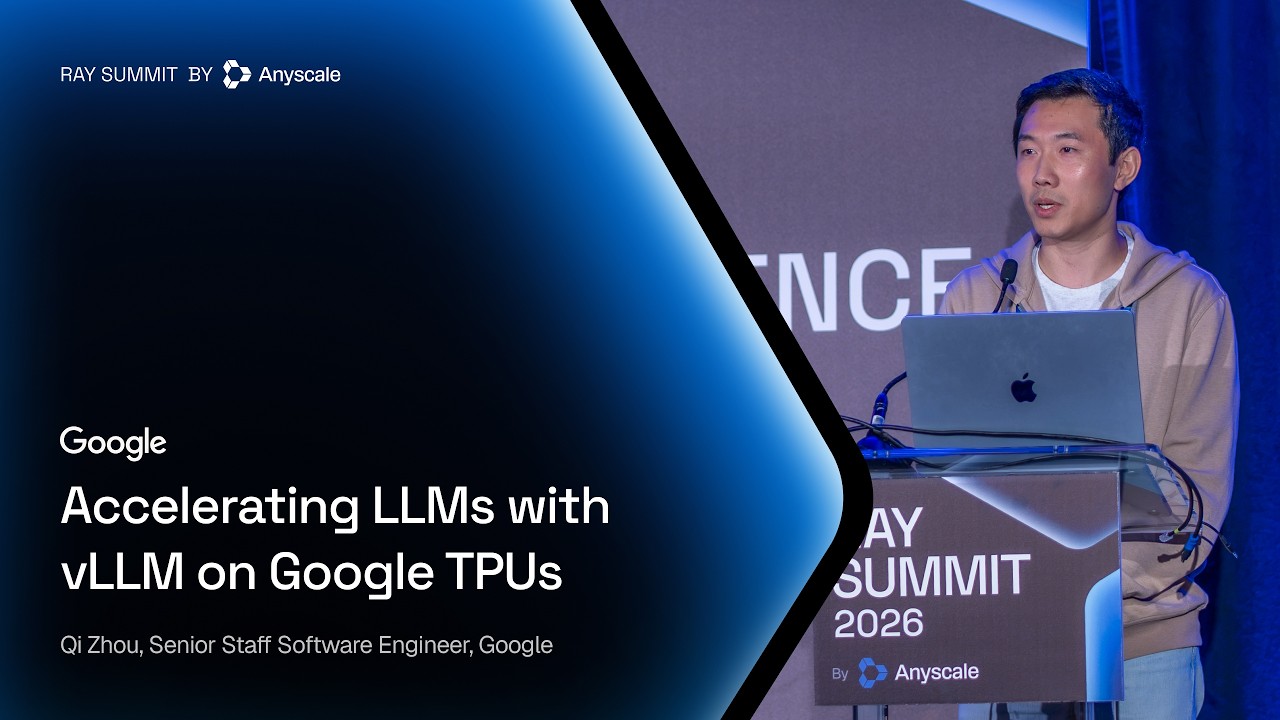
At Ray Summit 2026, Qi Zhou, Senior Staff Software Engineer at Google, explores the work to leverage Google TPUs with vLLM, orchestrated by Ray. He covers the performance and cost-efficiency benefits of TPU-based LLM serving, key enablers like the TorchTPU backend that brings a native PyTorch experience to TPUs, and insights from optimizing and scaling vLLM deployments.
You'll leave with the architectural approaches, the challenges overcome, and the outlook for high-performance, TPU-accelerated LLM inference with vLLM and Ray.
This session was part of the first vLLM Conference at Ray Summit, hosted by Inferact.
Liked this video? Check out other Ray Summit vLLM session recordings: youtube.com/playlist?list=PLXMguE8Nc9o4
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com
Large language models demand significant computational power for inference, and TPUs are becoming a first-class target for serving them.
At Ray Summit 2026, Qi Zhou, Senior Staff Software Engineer at Google, explores the work to leverage Google TPUs with vLLM, orchestrated by Ray. He covers the performance and cost-efficiency benefits of TPU-based LLM serving, key enablers like the TorchTPU backend that brings a native PyTorch experience to TPUs, and insights from optimizing and scaling vLLM deployments.
You'll leave with the architectural approaches, the challenges overcome, and the outlook for high-performance, TPU-accelerated LLM inference with vLLM and Ray.
This session was part of the first vLLM Conference at Ray Summit, hosted by Inferact.
Liked this video? Check out other Ray Summit vLLM session recordings: youtube.com/playlist?list=PLXMguE8Nc9o4
Subscribe to our YouTube channel to stay up-to-date on the future of AI: youtube.com/c/anyscale
🔗 Connect with us:
LinkedIn: linkedin.com/company/joinanyscale
X: https://x.com/anyscalecompute
Website: anyscale.com