Uploaded December 2016 | Updated November 2026, 3 days ago
A friendly introduction to neural networks and deep learning.
For a code implementation, check out this repo
github.com/luisguiserrano/manning/tree/master/Chapter_10_Neural_Networks
This is a follow up to the Introduction to Machine Learning video.
youtube.com/watch?v=IpGxLWOIZy4
Note: In this tutorial I use natural logarithms. If you used logarithms base 10, you may get different answers that I got, although at the end it doesn't matter, since using a different base for the logarithm just scales all the logarithms by a constant.
Announcement: New Book by Luis Serrano! Grokking Machine Learning. bit.ly/grokkingML
40% discount code: serranoyt
00:00 What is machine learning?
2:22 Gradient descent
5:07 Neural network
10:11 logistic regression
12:28 Probability
14:57 Activation Function
19:56 Error function
22:34 Node(Neuron)
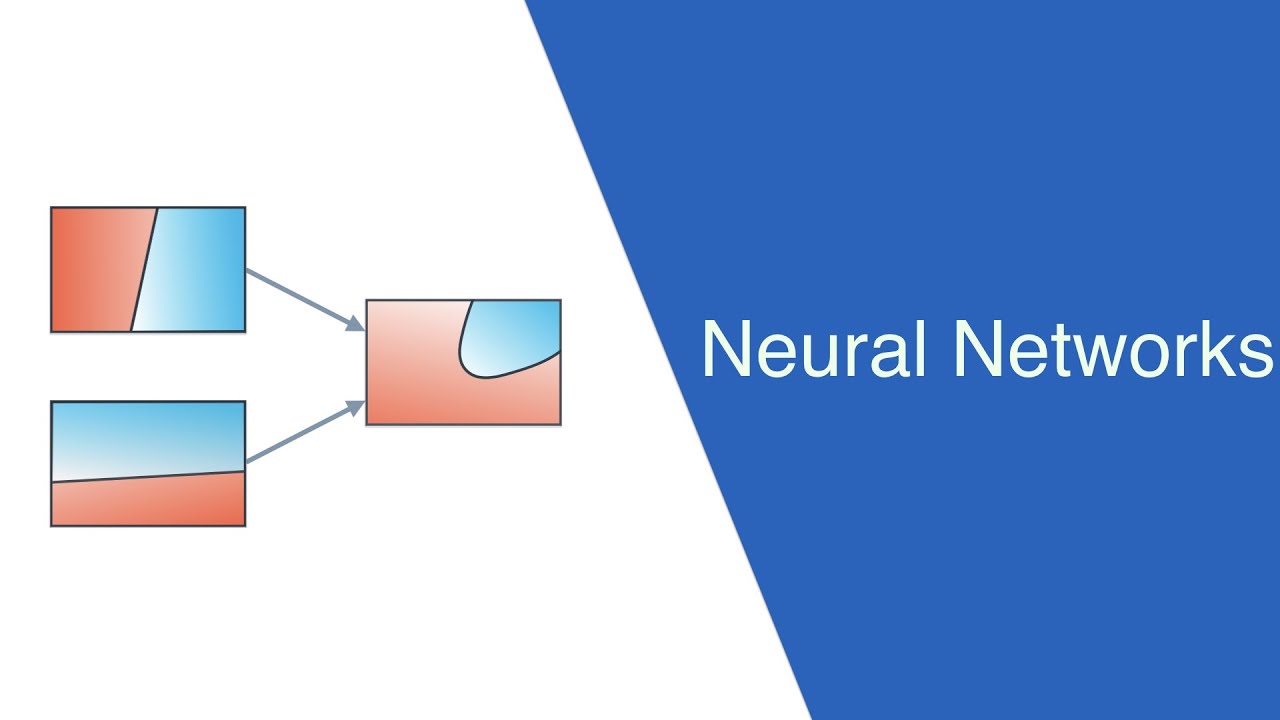
24:07 Non-linear regions
31:22 Deep neural network
A friendly introduction to neural networks and deep learning.
For a code implementation, check out this repo
github.com/luisguiserrano/manning/tree/master/Chapter_10_Neural_Networks
This is a follow up to the Introduction to Machine Learning video.
youtube.com/watch?v=IpGxLWOIZy4
Note: In this tutorial I use natural logarithms. If you used logarithms base 10, you may get different answers that I got, although at the end it doesn't matter, since using a different base for the logarithm just scales all the logarithms by a constant.
Announcement: New Book by Luis Serrano! Grokking Machine Learning. bit.ly/grokkingML
40% discount code: serranoyt
00:00 What is machine learning?
2:22 Gradient descent
5:07 Neural network
10:11 logistic regression
12:28 Probability
14:57 Activation Function
19:56 Error function
22:34 Node(Neuron)
24:07 Non-linear regions
31:22 Deep neural network