Uploaded March 2024 | Updated September 2026, 2 weeks ago
In today's data-driven world, scientific research generates vast amounts of data across various domains, posing challenges in storage, organization, processing, and analysis. The OptiData project aims to address these challenges by designing an efficient data management system tailored for large-scale scientific data.
During the 10-week project, our focus will be on optimizing data management processes, specifically data ingestion and storage. The project's feasibility within this timeframe is ensured by utilizing a single use case/dataset, carefully chosen to represent the characteristics and complexities typically encountered in scientific research.
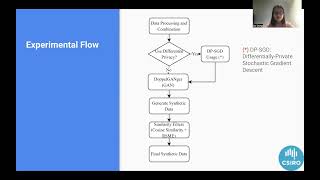
To handle the large data efficiently, we will develop innovative data compression techniques that reduce storage requirements without compromising data integrity or quality. This optimization will enable researchers to store and access larger volumes of data within limited storage resources. We will explore common compression algorithms like gzip and zlib, and also employ machine learning algorithms such as Autoencoders and GANs to analyse data patterns for specific scientific data types.
Additionally, intelligent data partitioning strategies will be employed to distribute large-scale data across multiple storage systems. By considering factors like data type, frequency of access, and computational requirements, we can optimize data retrieval and processing. Machine learning algorithms such as Reinforcement Learning and Collaborative Filtering will help develop intelligent partitioning algorithms based on historical data usage patterns, enhancing data accessibility and retrieval performance.
To ensure the project's feasibility, we will focus on a specific use case, such as climate science or astronomy. This use case will provide a realistic representation of the challenges faced in managing large-scale scientific data within the chosen domain. For example, in climate science, we may aim to study the impact of climate patterns on crop yields or predict extreme weather events based on historical data. By analysing data optimization techniques in such domain, students will gain valuable skills in data management, algorithm development, and system design.
Throughout the project, students will gain hands-on experience in developing data management systems and applying advanced technologies such as data compression and machine learning. They will learn practical skills in data optimization, algorithm development, and system design. Additionally, they will have the opportunity to analyse the performance of their proposed solutions, gather metrics, and provide valuable recommendations for improving data management practices.
In conclusion, the OptiData project aligns with machine learning and data management priorities by addressing challenges in scientific data storage, organization, and analysis. It contributes to domain knowledge and supports Australian science, research, and innovation goals by optimizing data management processes and facilitating more efficient scientific research.
In today's data-driven world, scientific research generates vast amounts of data across various domains, posing challenges in storage, organization, processing, and analysis. The OptiData project aims to address these challenges by designing an efficient data management system tailored for large-scale scientific data.
During the 10-week project, our focus will be on optimizing data management processes, specifically data ingestion and storage. The project's feasibility within this timeframe is ensured by utilizing a single use case/dataset, carefully chosen to represent the characteristics and complexities typically encountered in scientific research.
To handle the large data efficiently, we will develop innovative data compression techniques that reduce storage requirements without compromising data integrity or quality. This optimization will enable researchers to store and access larger volumes of data within limited storage resources. We will explore common compression algorithms like gzip and zlib, and also employ machine learning algorithms such as Autoencoders and GANs to analyse data patterns for specific scientific data types.
Additionally, intelligent data partitioning strategies will be employed to distribute large-scale data across multiple storage systems. By considering factors like data type, frequency of access, and computational requirements, we can optimize data retrieval and processing. Machine learning algorithms such as Reinforcement Learning and Collaborative Filtering will help develop intelligent partitioning algorithms based on historical data usage patterns, enhancing data accessibility and retrieval performance.
To ensure the project's feasibility, we will focus on a specific use case, such as climate science or astronomy. This use case will provide a realistic representation of the challenges faced in managing large-scale scientific data within the chosen domain. For example, in climate science, we may aim to study the impact of climate patterns on crop yields or predict extreme weather events based on historical data. By analysing data optimization techniques in such domain, students will gain valuable skills in data management, algorithm development, and system design.
Throughout the project, students will gain hands-on experience in developing data management systems and applying advanced technologies such as data compression and machine learning. They will learn practical skills in data optimization, algorithm development, and system design. Additionally, they will have the opportunity to analyse the performance of their proposed solutions, gather metrics, and provide valuable recommendations for improving data management practices.
In conclusion, the OptiData project aligns with machine learning and data management priorities by addressing challenges in scientific data storage, organization, and analysis. It contributes to domain knowledge and supports Australian science, research, and innovation goals by optimizing data management processes and facilitating more efficient scientific research.