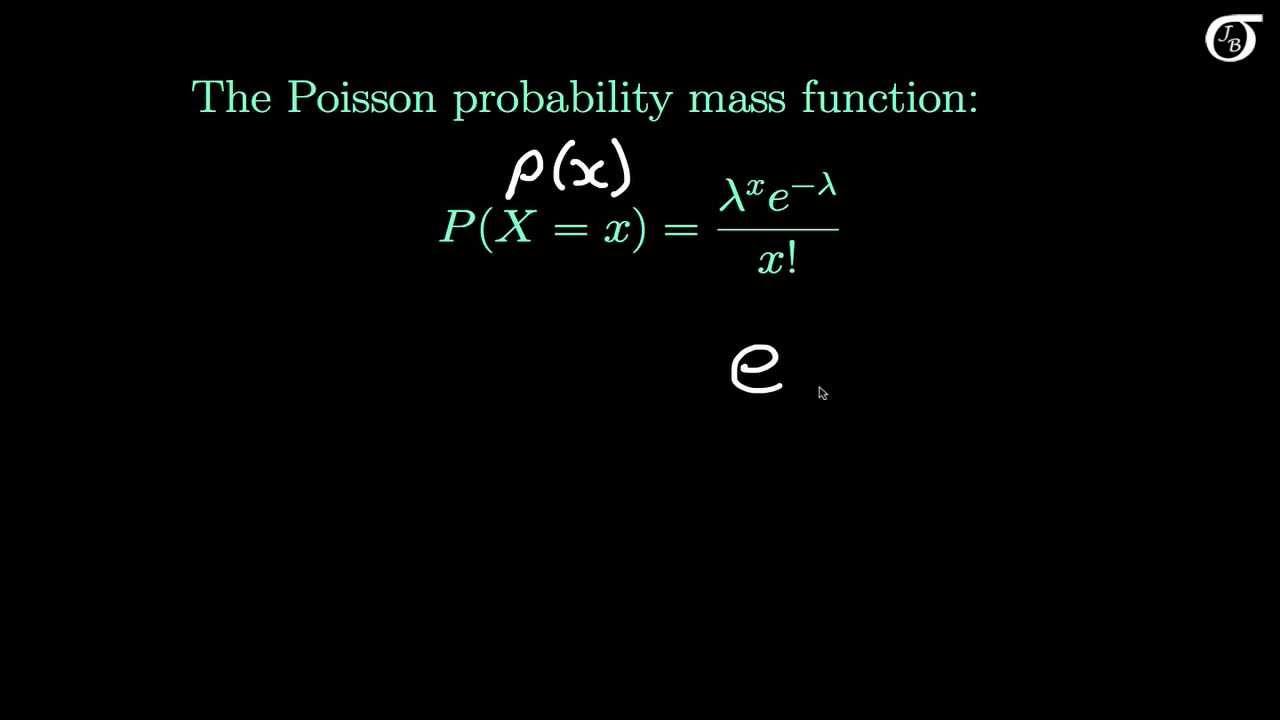An Introduction to the Poisson Distribution jbstatistics 2013-10-31 | An introduction to the Poisson distribution. I discuss the conditions required for a random variable to have a Poisson distribution. work through a simple calculation example, and briefly discuss the relationship between the binomial distribution and the Poisson distributions.Plutonium-239 example (an average of 2.3 radioactive decays per second).Finding the probability of exactly 3 radioactive decays in a 2 second period:dpois(3,2*2.3)[1] 0.1630676Finding the probability of no more than 3 radioactive decays in a 2 second period:dpois(0,2*2.3)+dpois(1,2*2.3)+dpois(2,2*2.3)+dpois(3,2*2.3)[1] 0.3257063orppois(3,2*2.3)[1] 0.3257063
What I envision a virtual work meeting at D2L (Brightspace) to be like (jk, obv) jbstatistics 2022-03-09 | Todd meets with his supervisor at D2L (Brightspace) to discuss priorities going forward.(I'll get back to stats videos soon. This one's mainly for fun, but inspired by a decade of frustration. In case it's not obvious, I play both parts.)D2L (Brightspace) quizzes do not allow an instructor to change the answer to a numeric response (arithmetic) question and regrade quiz attempts. There's a related problem on multiple-select questions. This has cost me personally at least a hundred hours over the last decade. Any fix is ad-hoc and time consuming, and leads to confusing feedback for students, inferior learning outcomes, and wasted time for instructors that could be used to do something productive.There are only so many possible explanations as to why D2L has not implemented this “feature”, despite pleas from instructors over the years. This video represents one possible explanation.
Basic Probability: The Multiplication Rule jbstatistics 2021-02-01 | An introduction to the multiplication rule. (I assume the viewer has an understanding of conditional probability and independence, but I do a very brief review of those concepts.) I introduce the multiplication rule for two events, work through a simple example, then discuss the multiplication rule for 3 events and how it generalizes to any number of events. I end with an example using the multiplication rule to find the probability of a 3 way intersection.Canadian demographic information is based on Statistics Canada numbers found here: www150.statcan.gc.ca/t1/tbl1/en/tv.action?pid=17100005010:18 Brief review of conditional probability and independence.1:39 Multiplication rule for two events2:49 Simple urn example4:32 Cautionary example6:43 Multiplication rule for 3 events7:35 Example involving Canadian demographics
Linear Transformations (in a Descriptive Statistics Setting) jbstatistics 2021-02-01 | I discuss linear transformations, in the context of descriptive statistics. I discuss what a linear transformation is, give an example, discuss the effect of the linear transformation on various summary statistics, and work through a numerical example.The temperature data is from here:climate.weather.gc.ca/climate_data/daily_data_e.html?StationID=51459&timeframe=2&StartYear=1840&EndYear=2021&Day=22&Year=2020&Month=7#(The original data was given in Celsius, but I converted it to Fahrenheit for use in this video.) 0:00 Introduction and example1:36 Illustration of the effect of the additive constant on measures of central tendency and variability.3:58 Illustration of the effect of the multiplicative constant on measures of central tendency and variability.6:52 Formulas for the new mean, standard deviation, and variance after the linear transformation.7:50 A numerical example of the effect of a linear transformation on the mean, median, standard deviation, and variance (converting temperatures from Fahrenheit to Celsius).R code to calculate the mean and standard deviation for the examples:mean(c(3,4,5))[1] 4sd(c(3,4,5))[1] 1
An Introduction to Boxplots jbstatistics 2021-02-01 | An introductory to boxplots. (I do not carry out any calculations, this video is about interpreting boxplots.) I discuss the basics, an applied example, give a few illustrations of histograms and boxplots under symmetry and skewness, then briefly discuss how large samples often lead to a large number of outliers in a boxplot. Source of the jumping fish example: Brunt et al. (2016). Amphibious fish jump better on land after acclimation to a terrestrial environment. Journal of Experimental Biology, 219:3204-3207. (Thanks to the authors for supplying the raw data!)Link to a National Geographic YouTube video of these fish jumping: https:// youtu.be/TZzW1pfwmfU0:00 The basics6:00 Real world example8:10 What boxplots tend to look like under symmetry and skewness.10:44 Brief discussion of outliers and large sample sizes.
On average, what proportion of sample means would a randomly selected 95% CI for mu capture? jbstatistics 2019-04-10 | This one's inspired by a common confidence interval misinterpretation.(This is a bit of a different video for me, and if you're just looking for help with specific topics in a statistics course, you may not find it helpful. But there's some good stuff in here.)Here I address what might seem at first like bit of a strange or uninformative question: In repeated sampling from a normally distributed population, on average what proportion of sample means would a randomly selected 95% CI for mu capture? I work through the calculations, then I discuss how this notion relates to bad confidence interval interpretations and reproducibility* studies.This was inspired by a bad confidence interval interpretation that I heard a number of years ago (and have heard variants of ever since), where, when interpreting a 95% confidence interval for the population mean, the individual stated:``If you repeat the same study a million times, then the mean of each one of those samples should fall in the interval 95% of the time.'' [Edited slightly to improve the readability.]This is a poor interpretation of the interval, and simply untrue. It's just not the case. So, then, what is the probability a randomly selected 95% confidence interval for mu captures the mean of another sample of the same size from the same population?This has applications in reproducibility* studies, and I briefly discuss that after working through the calculations. My discussion is not intended to be a complete discussion of issues in reproducibility*, just a brief discussion of how the question I answer relates.*In this video I use "reproducible" and "replicable" interchangeably. I know there has been much discussion in some circles of differences between those terms. Apologies if you find my casual use of these terms problematic or misleading.Reference for the paper I bring up:Open Science Collaboration. (2015). Estimating the reproducibility of psychological science. \textit{Science}, 349(6251), 1--8.Reference for a different discussion about how there is extra variability when comparing two statistics, and why the results found in the reference above might not be as bad as they appear at first blush:Patil P., Peng R. D., Leek J. T. (2016). What should researchers expect when they replicate studies? A statistical view of replicability in psychological science. Perspect. Psychol. Sci. 11 539--544. 10.1177/1745691616646366
Deriving the mean and variance of the least squares slope estimator in simple linear regression jbstatistics 2019-04-01 | I derive the mean and variance of the sampling distribution of the slope estimator (beta_1 hat) in simple linear regression (in the fixed X case). I discuss the typical model assumptions, and discuss where we use them as I carry out the derivations. The derivations are carried out using summation notation (no matrices).At the end, I briefly discuss the normality assumption, and how that leads to beta_1 hat being normally distributed. While I do discuss the real deal there, I go over it fairly quickly, as the main point of the video is deriving E(beta_1 hat) and Var(beta_1 hat). Note that any time I use "errors" or "error terms" in this video, I am referring to the theoretical error terms (the epsilons) and not observed residuals from sample data.Time stamps:0:00 Brief discussion the simple linear regression model, assumptions, and some tools we will use.2:58 Deriving E(beta_1 hat)5:06 Deriving Var(beta_1 hat)8:49 Discussion of normality of beta_1 hat.
The Law of Total Probability jbstatistics 2019-03-30 | I discuss the Law of Total Probability. I begin with some motivating plots, then move on to a statement of the law, then work through two examples.
P(A) = P(A and B) + P(A and Bc) jbstatistics 2019-03-30 | A quick video to illustrate that P(A) = P(A and B) + P(A and Bc), and work through a simple conditional probability example that makes use of this identity.I know from experience that some of my students have trouble seeing this (especially when it comes up in a formulaic approach to a problem), and I wanted to have a video that I could point them to.My Law of Total Probability video is here: youtu.be/7t9jyikrG7w
Deriving the least squares estimators of the slope and intercept (simple linear regression) jbstatistics 2019-03-22 | I derive the least squares estimators of the slope and intercept in simple linear regression (Using summation notation, and no matrices.) I assume that the viewer has already been introduced to the linear regression model, but I do provide a brief review in the first few minutes. I assume that you have a basic knowledge of differential calculus, including the power rule and the chain rule. If you are already familiar with the problem, and you are just looking for help with the mathematics of the derivation, the derivation starts at 3:26. At the end of the video, I illustrate that sum(X_i-X bar)(Y_i - Y bar) = sum X_i(Y_i - Y bar) =sum Y_i(X_i - X bar) , and that sum(X_i-X bar)^2 = sum X_i(X_i - X bar).There are, of course, a number of ways of expressing the formula for the slope estimator, and I make no attempt to list them all in this video.
Proof that if events A and B are independent, so are Ac and B (and A and Bc) jbstatistics 2019-03-22 | Here I prove that if events A and B are independent, so are A complement and B. (And A and B complement, of course, since which event we call A and which we call B is arbitrary.) Looking for a proof that if A and B are independent, so are their complements? That's here: youtu.be/bnDpZNlVZ3k
Proof that if two events are independent, so are their complements. jbstatistics 2019-03-20 | Just getting warmed up.Here I prove that if events A and B are independent, so are Ac and Bc. I make use of De Morgan's Laws, without offering a formal proof of that part (but I do provide a brief Venn diagram justification of the needed bit). More probability and statistics videos will follow.
Independent Events (Basics of Probability: Independence of Two Events) jbstatistics 2018-02-09 | An introduction to the concept of independent events, pitched at a level appropriate for the probability section of a typical introductory statistics course. I give the definition of independence, work through some simple examples, and attempt to illustrate the meaning of independence in various ways. (Note: I use the phrase "not independent" rather than "dependent" almost exclusively. There is nothing wrong with calling events dependent when they are not independent, but I prefer to use "not independent" for a couple of reasons.) (I'm on a bit of a probability run, but looking forward to getting back to statistics videos in the near future.)This one turned out to be long, as I had a number of points I wanted to discuss. Here's the breakdown:0:20. The definition of independence, showing what that means in terms of conditional probability, and some hand-waving discussion of what independence means.3:48. Very simple examples (P(A) = x, P(B) = y, etc.).6:20. Die rolling examples.10:03. Discussion of the fact that if A and B are independent, so are (A and Bc), (Ac and B), and (Ac and Bc), including a hand-waving justification. The previous example involved a lead-in to this. (The hand-waving is legit happening behind the scenes.)11:15. Visual illustration of independence.14:39. Playing card examples.18:19. Discussion of how we sometimes *assume* events are independent (e.g. heads on first toss of a fair coin, heads on second toss), and how this is an *assumption*, and not something that can be proven mathematically (despite what you might see elsewhere).19:24. Discussion of how the term "independent" can have a different meaning in everyday English compared to its usage in probability, and how that is sometimes a cause for confusion.
Conditional Probability Example Problems jbstatistics 2018-02-01 | Conditional probability example problems, pitched at a level appropriate for a typical introductory statistics course. I assume that viewers have already been introduced to the concepts of conditional probability and independence, but I do review the concepts along the way. I work through some problems with the conditional probability formula explicitly, and some using the reduced sample space argument.The sudden death data is slightly modified from:Naneix et al. (2015). Sudden adult death: An autopsy series of 534 cases with gender and control comparison. Journal of Forensic and Legal Medicine, 32:10-15.The data was pulled from their Figure 3, and I pooled the Abdominal/pelvian and undetermined groups into "other", to make the example work better visually and have it be easier to follow. I took some slight liberties here, as "undetermined" is not the same as "other". Conscious choice, y'all. Examples:0:58. An example using the conditional probability formula, where we are given P(A), P(B), and P(A U B).3:06: Die rolling. Everybody's fave. P(AUB|C).4:51. Two-way table, involving real data from above. Limited on interpretation, and focussing on finding various conditional probabilities.8:05. Conditional probability involving 3 events, visualized with a Venn diagram. P(A n C | B n C), P(B^c|A U C). 11:21. Example of determining whether P(A|B) = P(A), P(A|B) is less than P(A), or P(A|B) is greater than P(A), based on common knowledge and without being given probabilities. 13:00. Informal illustration that if P(A|B) is greater than P(A) then P(B|A) is greater than P(B), and if P(A|B) is less than P(A) then P(B|A) is less than P(B).14:40. If A is a subset of B, and P(A) is greater than 0, what can be said of P(A|B) and P(B|A)?
Basics of Probability: Unions, Intersections, and Complements jbstatistics 2018-02-01 | An introductory discussion of unions, intersections, and complements in the context of basic probability. I include a discussion of mutually exclusive events, as well as the addition rule. I work through a simple die rolling example, and also an example of a scenario where we randomly sample from a population of people, where some have diabetes and some have hypertension. The various scenarios are illustrated with Venn and Euler diagrams. (The percentages given in the video are loosely based on statistics for 50 year-old Canadian males.)
Dont watch this! (A t test example where nearly everything I say is wrong) jbstatistics 2018-01-26 | (Recorded in 2013, but misplaced and not released until now.)I work through an example of a one-sample t test on a mean, and (intentionally) make many false statements. Some of them might sound pretty reasonable. The lesson is: Get your statistics help from a reputable source!Wrong statements, with explanations:0:25: “Is the mean weight of cucumbers in my garden equal to 200 grams?” Not wrong, but it’s a bad example on a number of fronts: -It’s not a question anybody would ask.-The mean weight of cucumbers is in the garden is not going to equal exactly 200 grams, and we know that going in. -A t test might provide evidence on whether the true mean weight differs from 200 grams, but it’s not going to tell us that the true mean equals 200 grams.-If I really wanted to know the true mean weight (of the cucumbers that currently exist in my garden), I could probably pick them all and find out the true value. Or perhaps measure them on the vine with minimal error.0:55: “H_0: X bar = 200 grams.” Hypotheses never involve statistics or the value of statistics.1:25: “H_a” X bar greater than 200 grams.” The choice of alternative must never be based on the current sample’s data. It’s cheating to pick the alternative based on the observed data. And again, hypotheses never involve statistics or the values of statistics.1:40: “…we just pick alpha, our significance level, to be 0.05.” While this is fairly common practice, it usually doesn’t make any sense and definitely doesn’t make any sense here. Here, no decision needs to be made, and we would simply assess the strength of the evidence against H_0 using the p-value. (Some will disagree with me on this front.)2:00: “I could have picked any cucumbers in my garden, so every cucumber had the same chance of being picked.” While it is true that I could have picked any set of 4 cucumbers in the garden, that doesn’t imply they all had the same chance of being selected.2:04: “Yes, this was a simple random sample.” Even though there was likely some randomness involved, that doesn’t make it a simple random sample. A SRS has a very specific meaning, one that was almost surely not the case here. 2:23: “Knowing what the first cucumber weighed tells me nothing about what the second cucumber weighs. They were weighed independently, and the observations are therefore independent.” This is just silly. 2:37: “This is not an important question for a t test.” One of the assumptions of the one-sample t test is normality, and that assumption is very important for small sample sizes.2:51: “The t statistic has a t distribution, and we won’t need to concern ourselves with normality.” The t statistic has a t distribution only if H_0 is true and the assumptions (including normality) are true.3:00: “The t statistic is X bar - mu” The hypothesized mean (mu_0) is subtracted in the numerator of the test statistic, not the true mean mu (we don’t know mu, and if we did know it we wouldn’t be carrying out the test!). 3:08: “Mu is the true mean weight of cucumbers in my garden, and that’s simply given here in the null hypothesis.” While it is the case that mu represents the true mean weight of cucumbers in the garden, the value of 200 in the null hypothesis is the hypothesized mean (mu_0) and not the true mean mu.3:20: “Minus the true value of mu”. Again, we subtract the hypothesized mean, not the true mean.3:43: “For a t test, the degrees of freedom are always n-1.” For one-sample t tests on a single mean, like the one in this video, the degrees of freedom are n-1. But there are many different types of t tests, and the degrees of freedom vary between them.4:25: “The p-value is the probability of getting a sample mean that is at least as large as the observed sample mean of 214 grams.” This is a common misconception. If H_0 is true, and the assumptions are true, then the p-value is the probability of getting a t statistic at least as large as the one observed (1.12). For a t test like this one, this is not the same as the probability of getting a sample mean that is at least as large as 214 (even under Ho).4:33: “If I were to go out to my garden and get another 4 cucumbers, the probability of getting a mean weight of 214 grams or more would be 0.17.” This is possibly my favourite line in the video, as it sounds pretty good but is simply not true. We don’t know what this probability is, as it depends on unknown parameters (mu, sigma).4:46: “So we have pretty strong evidence that the null hypothesis is true, and that the true mean weight of cucumbers in my garden is actually 200 grams.” We found no meaningful evidence against the null hypothesis, but that most definitely doesn’t imply that it’s true. Lack of evidence against H_0 does not imply strong evidence for it. In addition, we essentially know going in that the true mean weight of cucumbers in the garden is not going to be *exactly* 200 grams.
De Morgans Laws (in a probability context) jbstatistics 2018-01-25 | A discussion of De Morgan's laws, in the context of basic probability. I illustrate De Morgan's laws using Venn diagrams, describe their meaning in a worded example, and show how they might be useful in a probability calculation.I will get back to statistics videos in the not-too-distant future. Right now, I'm hammering away on probability for a little while.
An Introduction to Conditional Probability jbstatistics 2018-01-23 | An introduction to conditional probability, pitched at a level appropriate for a typical introductory statistics course. I work through some simple examples in this introductory video, and a I briefly touch on the concept of independence in an example at the end of the video. I work through more examples (some a little harder) in my conditional probability example problems video: youtu.be/ES9HFNDu4Bs.
Are mutually exclusive events independent? jbstatistics 2018-01-21 | Are mutually exclusive events independent? I get asked variants of this question frequently, so it’s evident that some students confuse these two concepts. The one sentence summary: If A and B are mutually exclusive events, then they are independent if and only if P(A) = 0 or P(B) = 0. I take a more detailed look in this video.It's good to be back. I will post many more videos this year.
What Does Independence Look Like on a Venn Diagram? jbstatistics 2015-01-11 | Usually, Venn diagrams are not very useful for illustrating independence, as the sizes of the circles and their intersections have no meaning. It can help to illustrate independence if we force the area of each region to be equal to its probability of occurring. Independence is even easier to see if we represent the events with rectangles instead of circles. I illustrate these concepts in this video.All plots were created in R. The appropriate diameters of the circles and distance between the centres of the circles were calculated in R using the package venneuler. Not all plots in this video are officially called Venn diagrams.
The Expected Value and Variance of Discrete Random Variables jbstatistics 2014-07-15 | An introduction to the expected value and variance of discrete random variables. The formulas are introduced, explained, and an example is worked through. This is an updated and refined version of an earlier video. Those looking for the original version can find it at http://youtu.be/OvTEhNL96v0.
An Introduction to Discrete Random Variables and Discrete Probability Distributions jbstatistics 2014-07-04 | An introduction to discrete random variables and discrete probability distributions. A few examples of discrete and continuous random variables are discussed. This is an updated and revised version of an earlier video. Those looking for my original Intro to Discrete Random Variables video can find it at: http://youtu.be/0P5WRKihQ4E
Inference for the Ratio of Variances: How Robust are These Procedures? jbstatistics 2014-06-25 | A discussion of the effect of violations of the normality assumption on confidence intervals for the ratio of variances. The effects of different violations of the normality assumption are investigated through simulation. The quick summary: These procedures are very sensitive to violations of the normality assumption, and often perform very poorly when the normality assumption is violated.This video is very similar in content and results to my video that investigates the effect of violations of the normality assumption on inference procedures for a single variance.
Inference for a Variance: How Robust are These Procedures? jbstatistics 2014-06-22 | A discussion of the effect of violations of the normality assumption on confidence intervals for a variance. The effects of different violations of the normality assumption are investigated through simulation. The quick summary: These procedures are very sensitive to violations of the normality assumption, and often perform very poorly when the normality assumption is violated.
The Sampling Distribution of the Ratio of Sample Variances jbstatistics 2014-06-20 | A discussion of the sampling distribution of the ratio of sample variances. I begin by discussing the sampling distribution of the ratio of sample variances when sampling from normally distributed populations, and then illustrate, through simulation, the sampling distribution of the ratio of sample variances for two other distributions.
Inference for Two Variances: An Example of a Confidence Interval and a Hypothesis Test jbstatistics 2014-06-15 | I work through an example of a confidence interval and a hypothesis test for the ratio of population variances, using F procedures that are based on the assumption of normally distributed populations. The example in this video involves tail lengths of male and female lizards. The summary statistics and distributions of the tail lengths are from Table 1 and Figure 2 in:Qu et al. (2011). Sexual dimorphism and female reproduction in twosympatric toad-headed lizards, Phrynocephalus frontalisand P. versicolor (Agamidae). Animal Biology. 61:139-151.
The Sampling Distribution of the Sample Variance jbstatistics 2014-06-15 | A discussion of the sampling distribution of the sample variance. I begin by discussing the sampling distribution of the sample variance when sampling from a normally distributed population, and then illustrate, through simulation, the sampling distribution of the sample variance for a few other distributions.
Deriving a Confidence Interval for the Ratio of Two Variances jbstatistics 2014-06-09 | I derive the appropriate formula for a confidence interval for the ratio of two population variances (when we are sampling from normally distributed populations). I do not do any calculations or look at any examples in this video, I simply derive the appropriate confidence interval formula.
An Introduction to Inference for the Ratio of Two Variances jbstatistics 2014-06-08 | An introduction to confidence intervals and hypothesis tests for the ratio of two population variances (using F procedures based on the assumption of normally distributed populations). I introduce the methods, and take a quick look at an example and discuss the results. I don't work through any calculations in this video, but I have another video in which I work through a complete example. The summary statistics and distribution of the 2D:4D ratios were estimated from Figures 1, 2, and 3 in:Ozener et al. (2014). Inbreeding Is Associated with Lower 2D:4D Digit Ratio. American Journal of Human Biology. 26:183-188.
Deriving a Confidence Interval for a Variance (Assuming a Normally Distributed Population) jbstatistics 2014-06-04 | I derive the appropriate formula for a confidence interval for a population variance (when we are sampling from a normally distributed population). I do not do any calculations or look at any examples in this video, I simply derive the appropriate confidence interval formula. I work through an example at http://youtu.be/tsLGbpu\NPk
Inference for One Variance: An Example of a Confidence Interval and a Hypothesis Test jbstatistics 2014-05-28 | I work through an example of a confidence interval and a hypothesis test for a variance (using chi-square methods that are appropriate when sampling from a normally distributed population). The cereal data is from a sample of 15 bags of cereal that I collected and weighed.I have a video introduction to these procedures available at: http://youtu.be/lyd4V8DFCjM
An Introduction to Inference for One Variance (Assuming a Normally Distributed Population) jbstatistics 2014-05-27 | I discuss confidence intervals and hypothesis tests for a variance when sampling from a normally distributed population. I discuss the logic behind the procedures, discuss some characteristics of the sampling distribution of the sample variance, and give the appropriate formulas. I briefly discuss the results for an example problem, but I don't work through any of the calculations in this video. (I have another video in which I work through a complete example -- it's available at http://youtu.be/tsLGbpu_NPk)The fat content in deep fried chicken sandwiches is based on information from the USDA Nutrient Database: http://ndb.nal.usda.gov/ndb/foods/show/6781?fg=&man=&lfacet=&format=&count=&max=25&offset=&sort=&qlookup=mcdonald%27s+mcchicken
Inference for Two Proportions: An Example of a Confidence Interval and a Hypothesis Test jbstatistics 2014-05-19 | I work through an example of a confidence interval and a hypothesis test for the difference in population proportions (based on the normal approximation). The example involves an experiment investigating a possible effect of magnetic pulse on the ability of homing pigeons to navigate. The data used in this video is taken from:Holland et al. (2013). A magnetic pulse does not affect homing pigeon navigation: a GPS tracking experiment. The Journal of Experimental Biology, 216: 2192-2200. See the article for further details on the experiment. If you want more information about these procedures, I have a video introduction to inference procedures to two proportions available at: http://youtu.be/g0at6LpYvHc.
An Introduction to Inference for Two Proportions jbstatistics 2014-05-17 | I discuss the sampling distribution of the difference in sample proportions, and confidence intervals and hypothesis tests for the difference in population proportions (using large sample Z procedures based on the normal approximation). The male birth rate data is from:Koshy et al. (2010). Parental smoking and increased likelihood of female births. Annals of Human Biology, 37(6): 789-800.
Confidence Intervals for a Proportion: Determining the Minimum Sample Size jbstatistics 2014-05-16 | I discuss determining the minimum sample size required to achieve a given margin of error when estimating a population proportion. (For intervals based on the normal approximation.)
The Sampling Distribution of the Sample Proportion jbstatistics 2014-05-10 | A discussion of the sampling distribution of the sample proportion. I discuss how the distribution of the sample proportion is related to the binomial distribution, discuss its mean and variance, and illustrate that the sample proportion is approximately normally distributed for large sample sizes.
Inference for a Proportion: An Example of a Confidence Interval and a Hypothesis Test jbstatistics 2014-05-04 | I work through an example of a confidence interval and a hypothesis test for a single proportion, using normal approximation methods (Z test and confidence interval).The data on the proportion of male births is from:Koshy et al. (2010). Parental smoking and increased likelihood of female births. Annals of Human Biology, 37(6): 789--800.
An Introduction to Inference for a Proportion jbstatistics 2014-05-04 | An introduction to inference procedures for a single proportion. I discuss confidence intervals and hypothesis testing methods for a single proportion (based on the normal approximation).
Poisson or Not? (When does a random variable have a Poisson distribution?) jbstatistics 2014-01-31 | A not-too-technical look at the conditions required for a random variable to have a Poisson distribution. It can be difficult to determine whether a random variable actually has a Poisson distribution, so here I look at a few examples and some visual illustrations that may help. There are no probability calculations carried out in this video. I assume that the viewer has already been introduced to the Poisson distribution, but I do a brief review at the start.
An Introduction to the Geometric Distribution jbstatistics 2014-01-30 | An introduction to the geometric distribution. I discuss the underlying assumptions that result in a geometric distribution, the formula, and the mean and variance of the distribution. I work through an example of the calculations and then discuss the cumulative distribution function.For those using R, here is the R code for the example in this video:NB R uses a different definition of the random variable than I do here. I define the random variable X to be the number of trials required to get the first success. R defines the random variable to be the number of *failures* before getting the first success (let's call this Y). Then Y = X - 1, and we'll have to make this adjustment when using dgeom, pgeom, or rgeom. Some might find this confusing, and if you do, don't use these functions.Sampling from a large population where 30% have CPR training until we get the first person with CPR training.Finding the probability that it happens on the sixth person sampled:(.3)*(.7)^5[1] 0.050421ordgeom(6-1,.3)[1] 0.050421Finding the probability that it happens on or before the third person sampled:.3+.3*.7+.3*.7^2[1] 0.657or1-.7^3[1] 0.657orpgeom(3-1,.3)[1] 0.657
The Sample Variance: Why Divide by n-1? jbstatistics 2014-01-28 | An informal discussion of why we divide by n-1 in the sample variance formula. I give some motivation for why we should divide by something less than n, and (casually) discuss the concept of degrees of freedom (in the context of the sample variance). I have another video with a mathematical proof that dividing by n-1 results in an unbiased estimator of the population variance, available at http://youtu.be/D1hgiAla3KI.
Proof that the Sample Variance is an Unbiased Estimator of the Population Variance jbstatistics 2014-01-26 | A proof that the sample variance (with n-1 in the denominator) is an unbiased estimator of the population variance.In this proof I use the fact that the sampling distribution of the sample mean has a mean of mu and a variance of sigma^2/n. If you need that to be shown as well, I show that in this video: http://youtu.be/7mYDHbrLEQo.
Z-Scores (As a Descriptive Measure of Relative Standing) jbstatistics 2014-01-25 | An introduction to z-scores as a descriptive measure of relative standing. (I don't do any probability calculations in this video.) I do a simple calculation example, discuss the empirical rule in the context of z-scores, and illustrate what the z-score tells us about how large or small an observation is. The mean and standard deviation of the heights of American males is based on information from:McDowell MA, Fryar CD, Ogden CL, FlegalKM. Anthropometric reference data for childrenand adults: United States, 2003-2006.National health statistics reports; no 10.Hyattsville, MD: National Center for HealthStatistics. 2008.(The mean is taken directly from this document, and the standard deviation is estimated based on the given percentiles.)
Measures of Central Tendency jbstatistics 2014-01-19 | A brief introduction to measures of central tendency. The mean, median, and mode are introduced and calculated for a simple example. The relationship between the mean and median for different shapes of distributions is then discussed. The guinea pig survival time data can be found in:Doksum, K. (1974). Empirical probability plots and statistical inferencefor nonlinear models in the two-sample case. Annals of Statistics, 2:267--277.
Measures of Variability (Variance, Standard Deviation, Range, Mean Absolute Deviation) jbstatistics 2014-01-17 | An introduction to measures of variability. I discuss the range, mean absolute deviation, variance, and standard deviation, and work through a simple example of calculating these quantities. I then discuss interpreting the standard deviation, including a brief discussion of the empirical rule.In this video it is assumed that we are dealing with sample data, and not data representing the entire population. This will be the case the vast majority of the time in practice. The birth weight data is from random sample of 1000 males drawn from Table 7-2 (Live births, by birth weight and geography -- Males) of the Statistics Canada publication 84F0210X, available at \url{http://www.statcan.gc.ca/pub/84f0210x/2009000/t011-eng.htm}.
An Introduction to the t Distribution (Includes some mathematical details) jbstatistics 2013-11-22 | An introduction to the t distribution, a common continuous probability distribution. I discuss how the t distribution arises, its pdf, its mean and variance, and its relationship to the standard normal distribution. I illustrate the relationship between the t distribution and the standard normal distribution through a series of plots. This video contains some mathematical details regarding the t distribution (the pdf, mean, variance, how the distribution arises). Depending on your needs, this may not be important to you. In that event, I also have a video with a less technical introduction to the t distribution, available at http://youtu.be/Uv6nGIgZMVw.
An Introduction to the Chi-Square Distribution jbstatistics 2013-11-21 | A brief introduction to the chi-square distribution. I discuss how the chi-square distribution arises, its pdf, mean, variance, and shape.
Deriving the Mean and Variance of the Sample Mean jbstatistics 2013-11-21 | I derive the mean and variance of the sampling distribution of the sample mean. I have another video where I discuss the sampling distribution of the sample mean and work through some example probability calculations. It's called "The Sampling Distribution of the Sample Mean", and it's available at: http://youtu.be/q50GpTdFYyI.
Discrete Probability Distributions: Example Problems (Binomial, Poisson, Hypergeometric, Geometric) jbstatistics 2013-11-10 | I work through a few probability examples based on some common discrete probability distributions (binomial, Poisson, hypergeometric, geometric -- but not necessarily in this order). I assume that you've been previously introduced to these distributions (although this isn't necessary for the geometric problem, as the probability is easily calculated from basic probability rules). Students sometimes have difficulty determining the appropriate distribution to use, so this video may give some help with the proper thought process.
Overview of Some Discrete Probability Distributions (Binomial,Geometric,Hypergeometric,Poisson,NegB) jbstatistics 2013-11-07 | A brief overview of some common discrete probability distributions (Bernoulli, Binomial, Geometric, Negative Binomial, Hypergeometric, Poisson). I discuss when these distributions arise and the relationships between them. I do not do any calculations in this video, or discuss the probability mass functions or other characteristics of the distributions. This video is simply an overview of the distributions that can either be used as a summary recap, or a quick introduction.