Uploaded June 2025 | Updated September 2026, 2 weeks ago
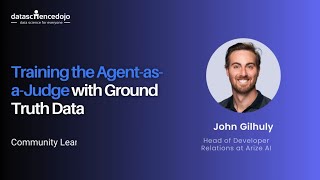
🛠️ How Do You Train an Agent as a Judge?
You train it similarly to how you'd tune an LLM-as-a-Judge:
Start with labeled ground truth data (human-labeled examples, prior outcomes, etc.)
Fine-tune tools or prompt templates to mirror human judgment across a variety of tasks
For each sub-tool (like “locate,” “read,” “ask”), you may:
Create synthetic training data
Use historical examples from actual agent runs
Validate performance incrementally before full integration
📌 Key Point: Training is modular—you often refine individual tools or steps, not the full pipeline at once.
🧠 Preventing Hallucinations
Ground truth comparison: Regularly compare the agent’s output against known-correct examples
Alignment scoring: Track how well it matches human consensus (as the Meta paper did)
Confidence scoring & flagging: Monitor output quality and intervene when certainty drops
Even the best judge agent will hallucinate sometimes—but you can detect and correct that drift if you’re watching closely.
🧩 Can You Build a Custom Agent-as-a-Judge?
Yes—absolutely. In fact, you have to:
Each judge agent needs custom tools and logic for its target domain (e.g., coding vs. customer support)
One-size-fits-all doesn't work; think of it more like building a QA team specialized for each product
You can also integrate these custom judge agents with:
MCP (Model Control Plane) for observability and routing
A2A (Agent-to-Agent) frameworks like Google’s for service-oriented architectures
📊 How Do You Monitor It?
Using tools like Arize, you can:
Trace and visualize judge agent behavior just like any other agent
Add custom evals to score correctness, confidence, or alignment
Create dashboards to track metrics over time:
Judge accuracy vs. ground truth
Latency, failure rate, or retrieval coverage
Confidence drop-offs, tool usage stats, etc.
⚙️ Example:
You can even run LLM-as-a-Judge on your Judge Agent, evaluating its output with prompts like:
“Given this task and the ground truth, did the judge agent correctly assess requirement fulfillment?”
Yes, it gets meta—but in a productive way.
🧵 Summary: It’s Agents Judging Agents All the Way Down
✅ You train judge agents with labeled data, just like you’d tune eval prompts
🧰 You equip them with a focused set of tools—usually fewer than you’d expect
📈 You evaluate and monitor them using the same frameworks you use for any agent
🧠 You still need humans in the loop (early on), but you scale trustworthy evaluation faster from there
🛠️ How Do You Train an Agent as a Judge?
You train it similarly to how you'd tune an LLM-as-a-Judge:
Start with labeled ground truth data (human-labeled examples, prior outcomes, etc.)
Fine-tune tools or prompt templates to mirror human judgment across a variety of tasks
For each sub-tool (like “locate,” “read,” “ask”), you may:
Create synthetic training data
Use historical examples from actual agent runs
Validate performance incrementally before full integration
📌 Key Point: Training is modular—you often refine individual tools or steps, not the full pipeline at once.
🧠 Preventing Hallucinations
Ground truth comparison: Regularly compare the agent’s output against known-correct examples
Alignment scoring: Track how well it matches human consensus (as the Meta paper did)
Confidence scoring & flagging: Monitor output quality and intervene when certainty drops
Even the best judge agent will hallucinate sometimes—but you can detect and correct that drift if you’re watching closely.
🧩 Can You Build a Custom Agent-as-a-Judge?
Yes—absolutely. In fact, you have to:
Each judge agent needs custom tools and logic for its target domain (e.g., coding vs. customer support)
One-size-fits-all doesn't work; think of it more like building a QA team specialized for each product
You can also integrate these custom judge agents with:
MCP (Model Control Plane) for observability and routing
A2A (Agent-to-Agent) frameworks like Google’s for service-oriented architectures
📊 How Do You Monitor It?
Using tools like Arize, you can:
Trace and visualize judge agent behavior just like any other agent
Add custom evals to score correctness, confidence, or alignment
Create dashboards to track metrics over time:
Judge accuracy vs. ground truth
Latency, failure rate, or retrieval coverage
Confidence drop-offs, tool usage stats, etc.
⚙️ Example:
You can even run LLM-as-a-Judge on your Judge Agent, evaluating its output with prompts like:
“Given this task and the ground truth, did the judge agent correctly assess requirement fulfillment?”
Yes, it gets meta—but in a productive way.
🧵 Summary: It’s Agents Judging Agents All the Way Down
✅ You train judge agents with labeled data, just like you’d tune eval prompts
🧰 You equip them with a focused set of tools—usually fewer than you’d expect
📈 You evaluate and monitor them using the same frameworks you use for any agent
🧠 You still need humans in the loop (early on), but you scale trustworthy evaluation faster from there