Uploaded January 2023 | Updated September 2026, 2 weeks ago
I have now sucessfully extended FluidX3D to multi-GPU, allowing to pool VRAM of multiple GPUs installed in a server node via domain decomposition, here 8x AMD Instinct MI200 64GB. The multi-GPU update is now published on GitHub: github.com/ProjectPhysX/FluidX3D
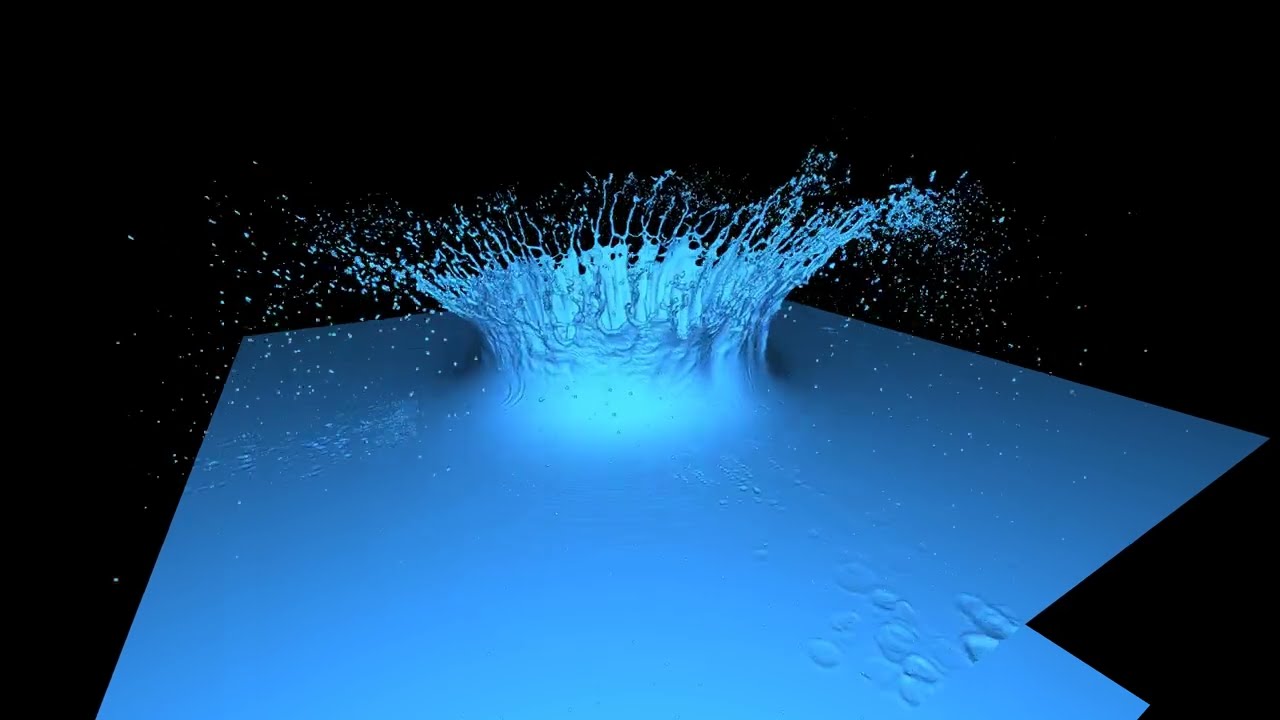
This is an 8 billion grid cell simulation of a d = 7 mm diameter terminal velocity (9.55 m/s) raindrop impact at 20° inclination, simulated for 3 milliseconds (34650 LBM time steps). The box is 5d x 5d x 4.25d and the pool height is 2d. For reproducibility: The dimensionless numbers for this setup are Re = 63618, We = 8864, Fr = 36.44, Ca = 0.1393, Bo = 6.674.
Velocity, density and fluid mass are solved at 8 billion lattice points (2122 x 2122 x 1804) with D3Q19 SRT and FP16S memory compression. The simulation requires 512 GB video memory and was conducted on 8x AMD Instinct MI200 GPUs at Jülich Supercomputing Centre (JSC) JURECA-DC-MI200. Combined compute+render time was 330 minutes. 4K60 rendering is done via domain decomposition rasterization, where each GPU renders only its own domain and the frames are seamlessly overlayed via their z-buffers. 4x 451 frames (6.3GB) are generated.
Find physical accuracy validation of the raindrop setup in this paper: doi.org/10.1186/s43591-021-00018-8
How is it possible to squeeze 8 billion grid points in only 512GB VRAM?
I'm using two techniques here, which together form the holy grail of lattice Boltzmann, cutting memory demand down to only 67 Bytes/node for D3Q19 LBM with the Volume-of-Fluid extension, or 1/3 of conventional codes:
1. In-place streaming with Esoteric-Pull. This almost cuts memory demand in half and slightly increases performance due to implicit bounce-back boundaries.
Paper: doi.org/10.3390/computation10060092
2. Decoupled arithmetic precision (FP32) and memory precision (FP16): all arithmetic is done in FP32, but LBM density distribution functions in memory are compressed to FP16. This almost cuts memory demand in half and almost doubles performance, without impacting overall accuracy for most setups.
Paper: researchgate.net/publication/362275548_Accuracy_and_performance_of_the_lattice_Boltzmann_method_with_64-bit_32-bit_and_customized_16-bit_number_formats
Graphics are done directly in FluidX3D with OpenCL, with the raw simulation data already residing in ultra-fast video memory. No volumetric data ever has to be copied to the CPU or hard drive, but only rendered frames instead. Once on the CPU side, a copy of the frame is made in memory and a thread is detached to handle the slow .png compression, all while the simulation is already continuing. At any time, about 16 frames are compressed in parallel on 16 CPU cores, while the simulation is running on GPU.
Paper: researchgate.net/publication/360501260_Combined_scientific_CFD_simulation_and_interactive_raytracing_with_OpenCL
Timestamps:
0:00 front view
0:07 side view
0:15 back view
0:22 top view
#CFD #GPU #FluidX3D #OpenCL
I have now sucessfully extended FluidX3D to multi-GPU, allowing to pool VRAM of multiple GPUs installed in a server node via domain decomposition, here 8x AMD Instinct MI200 64GB. The multi-GPU update is now published on GitHub: github.com/ProjectPhysX/FluidX3D
This is an 8 billion grid cell simulation of a d = 7 mm diameter terminal velocity (9.55 m/s) raindrop impact at 20° inclination, simulated for 3 milliseconds (34650 LBM time steps). The box is 5d x 5d x 4.25d and the pool height is 2d. For reproducibility: The dimensionless numbers for this setup are Re = 63618, We = 8864, Fr = 36.44, Ca = 0.1393, Bo = 6.674.
Velocity, density and fluid mass are solved at 8 billion lattice points (2122 x 2122 x 1804) with D3Q19 SRT and FP16S memory compression. The simulation requires 512 GB video memory and was conducted on 8x AMD Instinct MI200 GPUs at Jülich Supercomputing Centre (JSC) JURECA-DC-MI200. Combined compute+render time was 330 minutes. 4K60 rendering is done via domain decomposition rasterization, where each GPU renders only its own domain and the frames are seamlessly overlayed via their z-buffers. 4x 451 frames (6.3GB) are generated.
Find physical accuracy validation of the raindrop setup in this paper: doi.org/10.1186/s43591-021-00018-8
How is it possible to squeeze 8 billion grid points in only 512GB VRAM?
I'm using two techniques here, which together form the holy grail of lattice Boltzmann, cutting memory demand down to only 67 Bytes/node for D3Q19 LBM with the Volume-of-Fluid extension, or 1/3 of conventional codes:
1. In-place streaming with Esoteric-Pull. This almost cuts memory demand in half and slightly increases performance due to implicit bounce-back boundaries.
Paper: doi.org/10.3390/computation10060092
2. Decoupled arithmetic precision (FP32) and memory precision (FP16): all arithmetic is done in FP32, but LBM density distribution functions in memory are compressed to FP16. This almost cuts memory demand in half and almost doubles performance, without impacting overall accuracy for most setups.
Paper: researchgate.net/publication/362275548_Accuracy_and_performance_of_the_lattice_Boltzmann_method_with_64-bit_32-bit_and_customized_16-bit_number_formats
Graphics are done directly in FluidX3D with OpenCL, with the raw simulation data already residing in ultra-fast video memory. No volumetric data ever has to be copied to the CPU or hard drive, but only rendered frames instead. Once on the CPU side, a copy of the frame is made in memory and a thread is detached to handle the slow .png compression, all while the simulation is already continuing. At any time, about 16 frames are compressed in parallel on 16 CPU cores, while the simulation is running on GPU.
Paper: researchgate.net/publication/360501260_Combined_scientific_CFD_simulation_and_interactive_raytracing_with_OpenCL
Timestamps:
0:00 front view
0:07 side view
0:15 back view
0:22 top view
#CFD #GPU #FluidX3D #OpenCL


