Uploaded August 2026 | Updated September 2026, 2 weeks ago
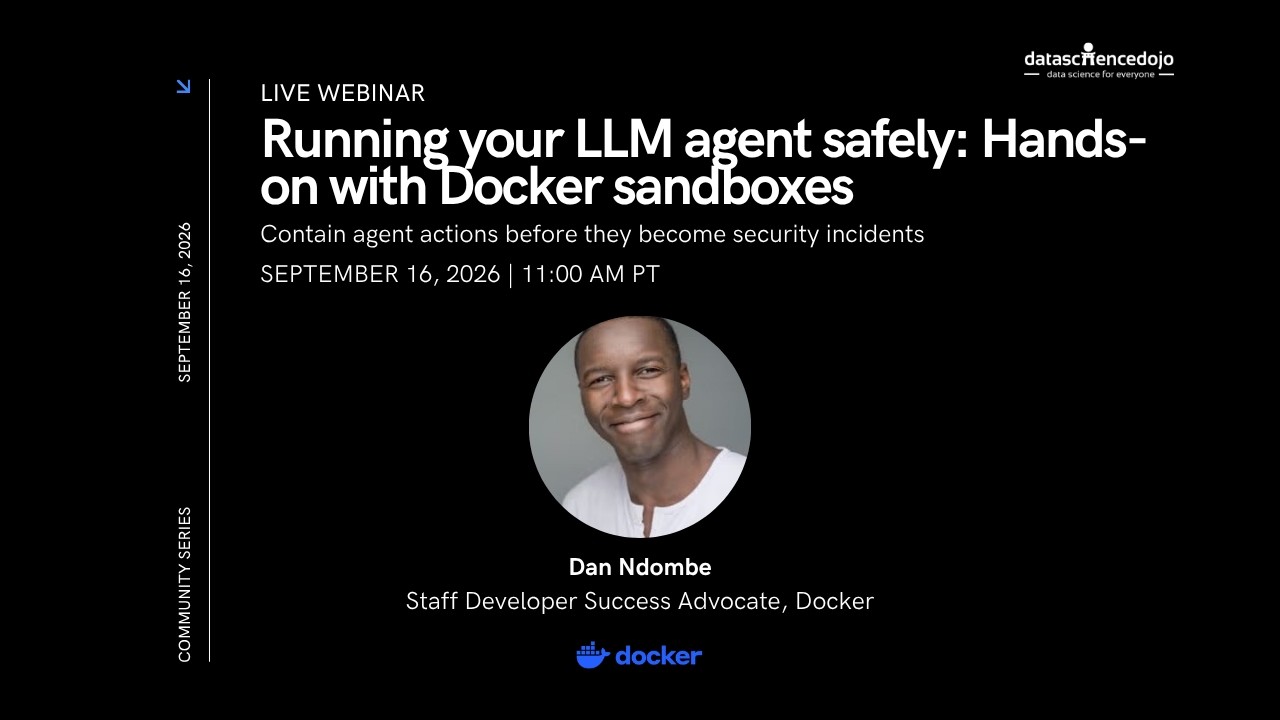
Once you understand how LLMs work, the next question is where you run one. The moment a model starts acting on its own — taking actions, calling tools, writing files, hitting APIs — that “where” becomes a security problem. This hands-on webinar walks you through running LLM agents safely using Docker Sandboxes (SBX). We’ll spin up a sandboxed agent runtime, give an agent a small task to complete, then explore how to tighten the policies around it so it can only do what it’s supposed to do.
Here’s the real-world pattern this solves: an agent given broad file or network access to “just get the task done” can just as easily read something it shouldn’t, write somewhere it shouldn’t, or call an API it shouldn’t. The fix isn’t smarter prompting — it’s containment. A sandbox lets the agent do its job while making the blast radius of a mistake (or a prompt injection) small and predictable.
We’ll build this live and take questions from the audience.
What You’ll Learn
- How Docker Sandboxes isolate an agent’s filesystem, network, and process access from the host
- How to spin up a sandboxed agent runtime and hand it a real task end-to-end
- How to read and tighten a sandbox policy — what to allow, what to block, and why
- Common ways “sandboxed” agents leak permissions anyway, and how to avoid them
- A reusable pattern you can take back to your own LLM and agent prototypes, no prior Docker experience required
Who Should Attend
This webinar is ideal for:
- Software engineers building or prototyping LLM-powered agents
- DevOps and platform engineers responsible for how AI workloads get deployed
- Security-minded developers who want practical, not theoretical, guardrails
- Technical leads evaluating how to safely scale agentic AI initiatives
- Anyone interested in agent security and containment strategies
No prior Docker experience is required.
Once you understand how LLMs work, the next question is where you run one. The moment a model starts acting on its own — taking actions, calling tools, writing files, hitting APIs — that “where” becomes a security problem. This hands-on webinar walks you through running LLM agents safely using Docker Sandboxes (SBX). We’ll spin up a sandboxed agent runtime, give an agent a small task to complete, then explore how to tighten the policies around it so it can only do what it’s supposed to do.
Here’s the real-world pattern this solves: an agent given broad file or network access to “just get the task done” can just as easily read something it shouldn’t, write somewhere it shouldn’t, or call an API it shouldn’t. The fix isn’t smarter prompting — it’s containment. A sandbox lets the agent do its job while making the blast radius of a mistake (or a prompt injection) small and predictable.
We’ll build this live and take questions from the audience.
What You’ll Learn
- How Docker Sandboxes isolate an agent’s filesystem, network, and process access from the host
- How to spin up a sandboxed agent runtime and hand it a real task end-to-end
- How to read and tighten a sandbox policy — what to allow, what to block, and why
- Common ways “sandboxed” agents leak permissions anyway, and how to avoid them
- A reusable pattern you can take back to your own LLM and agent prototypes, no prior Docker experience required
Who Should Attend
This webinar is ideal for:
- Software engineers building or prototyping LLM-powered agents
- DevOps and platform engineers responsible for how AI workloads get deployed
- Security-minded developers who want practical, not theoretical, guardrails
- Technical leads evaluating how to safely scale agentic AI initiatives
- Anyone interested in agent security and containment strategies
No prior Docker experience is required.