Uploaded October 2025 | Updated September 2026, 2 weeks ago
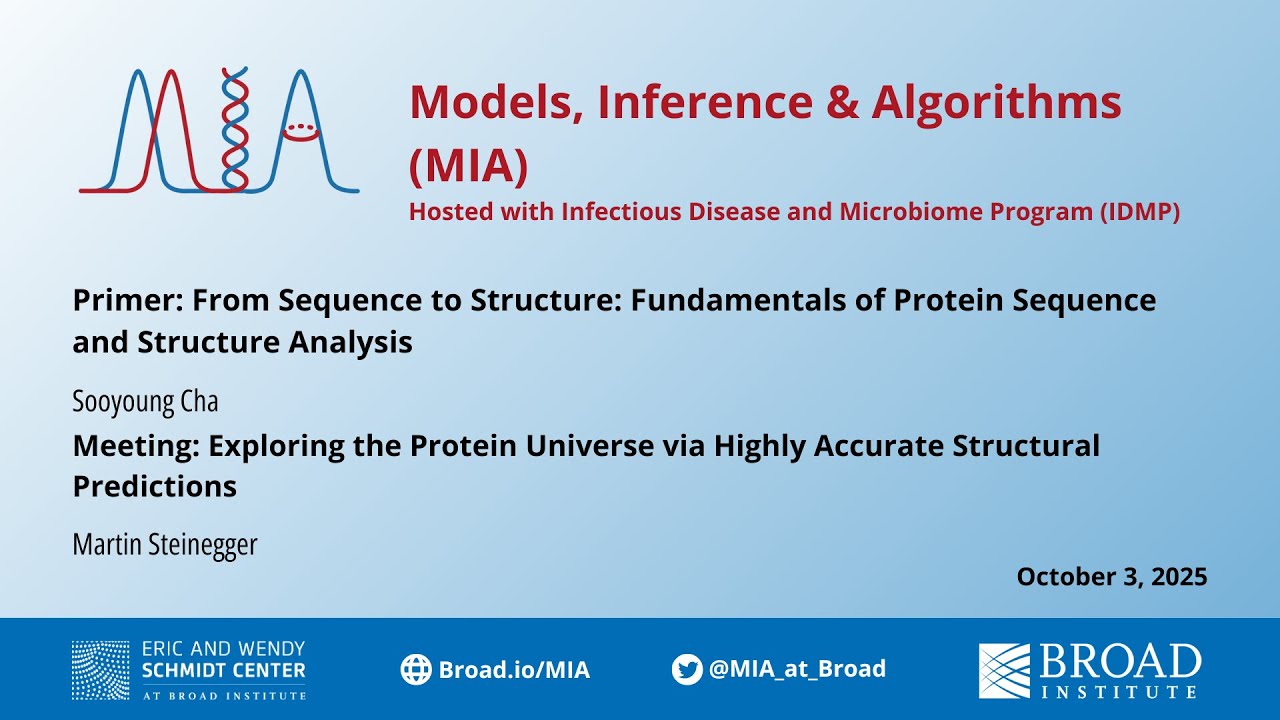
Models, Inference and Algorithms
September 24, 2025
Broad Institute of MIT and Harvard
Meeting: Exploring the Protein Universe via Highly Accurate Structural Predictions
Martin Steinegger
Seoul National University
Understanding the relationships and functions of proteins at a global scale is essential for unlocking new biological insights. Advances in next-generation structure predictors such as AlphaFold2 and ESMfold have yielded an unprecedented volume of protein structures, providing a powerful foundation for this challenge. In this talk, I will show how our computational methods MMseqs2, Foldseek and Folddisco enable extraction of biological insights from protein sequences and structures at nearly billion-scale, accelerating the way we explore protein function and evolution.
Additional resources:
Viral database: BFVD - bfvd.foldseek.com
Foldseek, Foldseek-multimer: foldseek.com
AlphaFold clusters: cluster.foldseek.com
AFESM: afesm.foldseek.com
Folddisco: folddisco.foldseek.com
The slides are available here: dropbox.com/scl/fi/0xrhdlhmzzetbnzttscy6/2025-Broad.pptx?rlkey=zy1k1hm5exubytptw9cqo5jl1&dl=0
Primer: From Sequence to Structure: Fundamentals of Protein Sequence and Structure Analysis
Sooyoung Cha
Seoul National University
Comparing protein sequences and structures is a cornerstone of computational biology, yet each approach comes with trade-offs in sensitivity and scalability. In this primer, we will begin with the fundamentals of sequence alignment and k-mer–based similarity search, highlighting both their strengths and limitations. We will then turn to structural alignment, introducing methods such as TM-align and motivating the need for alternative representations like 3Di. Building on this, we will briefly discuss Foldseek and how it enables fast structural comparisons at scale. Finally, we will explore the motivation for clustering protein sequences and structures, why it is necessary in large-scale datasets, and the different strategies that can be applied. Through simple illustrative examples, this primer aims to provide participants with the background knowledge needed to understand subsequent discussions on exploring the protein universe with accurate structural predictions.
For more information visit: https://www.broadinstitute.org/talks/...
Copyright Broad Institute, 2025. All rights reserved.
Models, Inference and Algorithms
September 24, 2025
Broad Institute of MIT and Harvard
Meeting: Exploring the Protein Universe via Highly Accurate Structural Predictions
Martin Steinegger
Seoul National University
Understanding the relationships and functions of proteins at a global scale is essential for unlocking new biological insights. Advances in next-generation structure predictors such as AlphaFold2 and ESMfold have yielded an unprecedented volume of protein structures, providing a powerful foundation for this challenge. In this talk, I will show how our computational methods MMseqs2, Foldseek and Folddisco enable extraction of biological insights from protein sequences and structures at nearly billion-scale, accelerating the way we explore protein function and evolution.
Additional resources:
Viral database: BFVD - bfvd.foldseek.com
Foldseek, Foldseek-multimer: foldseek.com
AlphaFold clusters: cluster.foldseek.com
AFESM: afesm.foldseek.com
Folddisco: folddisco.foldseek.com
The slides are available here: dropbox.com/scl/fi/0xrhdlhmzzetbnzttscy6/2025-Broad.pptx?rlkey=zy1k1hm5exubytptw9cqo5jl1&dl=0
Primer: From Sequence to Structure: Fundamentals of Protein Sequence and Structure Analysis
Sooyoung Cha
Seoul National University
Comparing protein sequences and structures is a cornerstone of computational biology, yet each approach comes with trade-offs in sensitivity and scalability. In this primer, we will begin with the fundamentals of sequence alignment and k-mer–based similarity search, highlighting both their strengths and limitations. We will then turn to structural alignment, introducing methods such as TM-align and motivating the need for alternative representations like 3Di. Building on this, we will briefly discuss Foldseek and how it enables fast structural comparisons at scale. Finally, we will explore the motivation for clustering protein sequences and structures, why it is necessary in large-scale datasets, and the different strategies that can be applied. Through simple illustrative examples, this primer aims to provide participants with the background knowledge needed to understand subsequent discussions on exploring the protein universe with accurate structural predictions.
For more information visit: https://www.broadinstitute.org/talks/...
Copyright Broad Institute, 2025. All rights reserved.