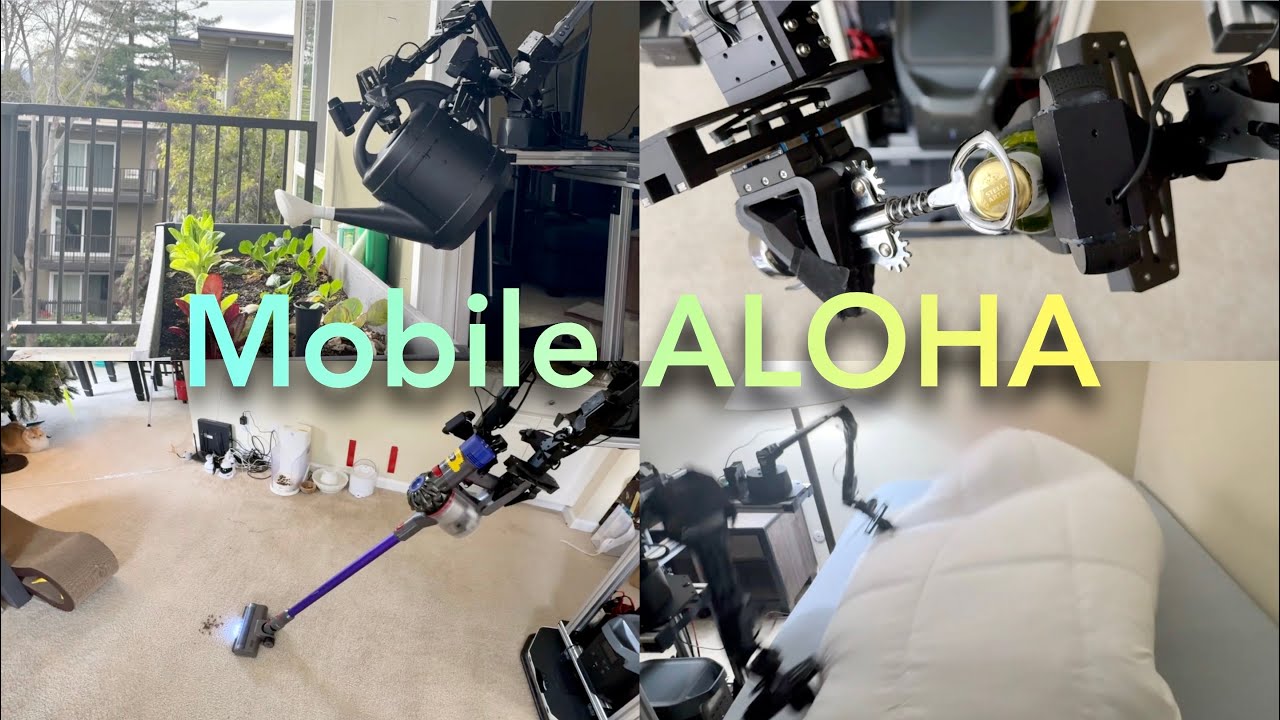
Mobile ALOHA: Your Housekeeping Robot Zipeng Fu 2024-01-04 | Project website: mobile-aloha.github.ioTeam at Stanford University: Zipeng Fu*, Tony Z. Zhao*, and Chelsea Finn(*The robot is teleoperated in the video. For autonomous robot skills, checkout our project website.)Abstract: Imitation learning from human demonstrations has shown impressive performance in robotics. However, most results focus on table-top manipulation, lacking the mobility and dexterity necessary for generally useful tasks. In this work, we develop a system for imitating mobile manipulation tasks that are bimanual and require whole-body control. We first present Mobile ALOHA, a low-cost and whole-body teleoperation system for data collection. It augments the ALOHA system with a mobile base, and a whole-body teleoperation interface. Using data collected with Mobile ALOHA, we then perform supervised behavior cloning and find that co-training with existing static ALOHA datasets boosts performance on mobile manipulation tasks. With 50 demonstrations for each task, co-training can increase success rates by up to 90%, allowing Mobile ALOHA to autonomously complete complex mobile manipulation tasks such as sauteing and serving a piece of shrimp, opening a two-door wall cabinet to store heavy cooking pots, calling and entering an elevator, and lightly rinsing a used pan using a kitchen faucet.
Stanford HumanPlus Humanoid learns to wear a Nike skateboard shoe, stand up and walk Zipeng Fu 2024-06-24 | HumanPlus: Humanoid Shadowing and Imitation from HumansProject website: humanoid-ai.github.ioTeam at Stanford University: Zipeng Fu*, Qingqing Zhao*, Qi Wu*, Gordon Wetzstein, Chelsea FinnAbstract: One of the key arguments for building robots that have similar form factors to human beings is that we can leverage the massive human data for training. Yet, doing so has remained challenging in practice due to the complexities in humanoid perception and control, lingering physical gaps between humanoids and humans in morphologies and actuation, and lack of a data pipeline for humanoids to learn autonomous skills from egocentric vision. In this paper, we introduce a full-stack system for humanoids to learn motion and autonomous skills from human data. We first train a low-level policy in simulation via reinforcement learning using existing 40-hour human motion datasets. This policy transfers to the real world and allows humanoid robots to follow human body and hand motion in real time using only a RGB camera, i.e. shadowing. Through shadowing, human operators can teleoperate humanoids to collect whole-body data for learning different tasks in the real world. Using the data collected, we then perform supervised behavior cloning to train skill policies using egocentric vision, allowing humanoids to complete different tasks autonomously by imitating human skills. We demonstrate the system on our customized 33-DoF 180cm humanoid, autonomously completing tasks such as wearing a shoe to stand up and walk, unloading objects from warehouse racks, folding a sweatshirt, rearranging objects, typing, and greeting another robot with 60-100% success rates using up to 40 demonstrations.
HumanPlus: Humanoid Shadowing of Human Motion Zipeng Fu 2024-06-13 | Stanford HumanPlus Robot: Humanoid Shadowing and Imitation from HumansProject website: humanoid-ai.github.ioTeam at Stanford University: Zipeng Fu*, Qingqing Zhao*, Qi Wu*, Gordon Wetzstein, Chelsea Finn Abstract: One of the key arguments for building robots that have similar form factors to human beings is that we can leverage the massive human data for training. Yet, doing so has remained challenging in practice due to the complexities in humanoid perception and control, lingering physical gaps between humanoids and humans in morphologies and actuation, and lack of a data pipeline for humanoids to learn autonomous skills from egocentric vision. In this paper, we introduce a full-stack system for humanoids to learn motion and autonomous skills from human data. We first train a low-level policy in simulation via reinforcement learning using existing 40-hour human motion datasets. This policy transfers to the real world and allows humanoid robots to follow human body and hand motion in real time using only a RGB camera, i.e. shadowing. Through shadowing, human operators can teleoperate humanoids to collect whole-body data for learning different tasks in the real world. Using the data collected, we then perform supervised behavior cloning to train skill policies using egocentric vision, allowing humanoids to complete different tasks autonomously by imitating human skills. We demonstrate the system on our customized 33-DoF 180cm humanoid, autonomously completing tasks such as wearing a shoe to stand up and walk, unloading objects from warehouse racks, folding a sweatshirt, rearranging objects, typing, and greeting another robot with 60-100% success rates using up to 40 demonstrations.
HumanPlus: Autonomous Skills from Imitating Humans Zipeng Fu 2024-06-13 | Stanford HumanPlus Robot: Humanoid Shadowing and Imitation from HumansProject website: humanoid-ai.github.ioTeam at Stanford University: Zipeng Fu*, Qingqing Zhao*, Qi Wu*, Gordon Wetzstein, Chelsea Finn Abstract: One of the key arguments for building robots that have similar form factors to human beings is that we can leverage the massive human data for training. Yet, doing so has remained challenging in practice due to the complexities in humanoid perception and control, lingering physical gaps between humanoids and humans in morphologies and actuation, and lack of a data pipeline for humanoids to learn autonomous skills from egocentric vision. In this paper, we introduce a full-stack system for humanoids to learn motion and autonomous skills from human data. We first train a low-level policy in simulation via reinforcement learning using existing 40-hour human motion datasets. This policy transfers to the real world and allows humanoid robots to follow human body and hand motion in real time using only a RGB camera, i.e. shadowing. Through shadowing, human operators can teleoperate humanoids to collect whole-body data for learning different tasks in the real world. Using the data collected, we then perform supervised behavior cloning to train skill policies using egocentric vision, allowing humanoids to complete different tasks autonomously by imitating human skills. We demonstrate the system on our customized 33-DoF 180cm humanoid, autonomously completing tasks such as wearing a shoe to stand up and walk, unloading objects from warehouse racks, folding a sweatshirt, rearranging objects, typing, and greeting another robot with 60-100% success rates using up to 40 demonstrations.
ALOHA Robot at Stanford University Zipeng Fu 2024-05-15 | Project Website: mobile-aloha.github.ioTeam at Stanford University: Zipeng Fu, Tony Z. Zhao, Chelsea FinnFilmed and Edited by Kurt HickmanAbstract: Imitation learning from human demonstrations has shown impressive performance in robotics. However, most results focus on table-top manipulation, lacking the mobility and dexterity necessary for generally useful tasks. In this work, we develop a system for imitating mobile manipulation tasks that are bimanual and require whole-body control. We first present Mobile ALOHA, a low-cost and whole-body teleoperation system for data collection. It augments the ALOHA system with a mobile base, and a whole-body teleoperation interface. Using data collected with Mobile ALOHA, we then perform supervised behavior cloning and find that co-training with existing static ALOHA datasets boosts performance on mobile manipulation tasks. With 50 demonstrations for each task, co-training can increase success rates by up to 90%, allowing Mobile ALOHA to autonomously complete complex mobile manipulation tasks such as sauteing and serving a piece of shrimp, opening a two-door wall cabinet to store heavy cooking pots, calling and entering an elevator, and lightly rinsing a used pan using a kitchen faucet.
Mobile ALOHA funny failures Zipeng Fu 2024-01-05 | Project website: mobile-aloha.github.ioTeam at Stanford University: Zipeng Fu*, Tony Z. Zhao*, and Chelsea FinnAbstract: Imitation learning from human demonstrations has shown impressive performance in robotics. However, most results focus on table-top manipulation, lacking the mobility and dexterity necessary for generally useful tasks. In this work, we develop a system for imitating mobile manipulation tasks that are bimanual and require whole-body control. We first present Mobile ALOHA, a low-cost and whole-body teleoperation system for data collection. It augments the ALOHA system with a mobile base, and a whole-body teleoperation interface. Using data collected with Mobile ALOHA, we then perform supervised behavior cloning and find that co-training with existing static ALOHA datasets boosts performance on mobile manipulation tasks. With 50 demonstrations for each task, co-training can increase success rates by up to 90%, allowing Mobile ALOHA to autonomously complete complex mobile manipulation tasks such as sauteing and serving a piece of shrimp, opening a two-door wall cabinet to store heavy cooking pots, calling and entering an elevator, and lightly rinsing a used pan using a kitchen faucet.
Mobile ALOHA - A Smart Home Robot - Compilation of Autonomous Skills Zipeng Fu 2024-01-03 | Mobile ALOHA: Learning Bimanual Mobile Manipulation with Low-Cost Whole-Body TeleoperationTeam at Stanford University: Zipeng Fu*, Tony Z. Zhao*, and Chelsea FinnProject website: mobile-aloha.github.ioAbstract: Imitation learning from human demonstrations has shown impressive performance in robotics. However, most results focus on table-top manipulation, lacking the mobility and dexterity necessary for generally useful tasks. In this work, we develop a system for imitating mobile manipulation tasks that are bimanual and require whole-body control. We first present Mobile ALOHA, a low-cost and whole-body teleoperation system for data collection. It augments the ALOHA system with a mobile base, and a whole-body teleoperation interface. Using data collected with Mobile ALOHA, we then perform supervised behavior cloning and find that co-training with existing static ALOHA datasets boosts performance on mobile manipulation tasks. With 50 demonstrations for each task, co-training can increase success rates by up to 90%, allowing Mobile ALOHA to autonomously complete complex mobile manipulation tasks such as sauteing and serving a piece of shrimp, opening a two-door wall cabinet to store heavy cooking pots, calling and entering an elevator, and lightly rinsing a used pan using a kitchen faucet.
Robot Parkour Learning (CoRL 2023) Zipeng Fu 2023-09-11 | Project website: robot-parkour.github.ioTeam: Ziwen Zhuang*, Zipeng Fu*, Jianren Wang, Christopher Atkeson, Sören Schwertfeger, Chelsea Finn, and Hang ZhaoAbstract: Parkour is a grand challenge for legged locomotion that requires robots to overcome various obstacles rapidly in complex environments. Existing methods can generate either diverse but blind locomotion skills or vision-based but specialized skills by using reference animal data or complex rewards. However, autonomous parkour requires robots to learn generalizable skills that are both vision-based and diverse to perceive and react to various scenarios. In this work, we propose a system for learning a single end-to-end vision-based parkour policy of diverse parkour skills using a simple reward without any reference motion data. We develop a reinforcement learning method inspired by direct collocation to generate parkour skills, including climbing over high obstacles, leaping over large gaps, crawling beneath low barriers, squeezing through thin slits, and running. We distill these skills into a single vision-based parkour policy and transfer it to a quadrupedal robot using its egocentric depth camera. We demonstrate that our system can empower two different low-cost robots to autonomously select and execute appropriate parkour skills to traverse challenging real-world environments.
[CoRL 2022 Oral Talk] Deep Whole-Body Control Zipeng Fu 2022-12-17 | [CoRL 2022 Oral Talk] Deep Whole-Body Control: Learning a Unified Policy for Manipulation and Locomotion (by Zipeng Fu, Xuxin Cheng and Deepak Pathak)More details can be found: manipulation-locomotion.github.ioPaper Abstract: An attached arm can significantly increase the applicability of legged robots to several mobile manipulation tasks that are not possible for the wheeled or tracked counterparts. The standard control pipeline for such legged manipulators is to decouple the controller into that of manipulation and locomotion. However, this is ineffective and requires immense engineering to support coordination between the arm and legs, error can propagate across modules causing non-smooth unnatural motions. It is also biological implausible where there is evidence for strong motor synergies across limbs. In this work, we propose to learn a unified policy for whole-body control of a legged manipulator using reinforcement learning. We propose Regularized Online Adaptation to bridge the Sim2Real gap for high-DoF control, and Advantage Mixing exploiting the causal dependency in the action space to overcome local minima during training the whole-body system. We also present a simple design for a low-cost legged manipulator, and find that our unified policy can demonstrate dynamic and agile behaviors across several task setups.
Coupling Vision and Proprioception for Navigation of Legged Robots (CVPR 2022) Zipeng Fu 2022-09-19 | Project webpage: navigation-locomotion.github.ioAbstract: We exploit the complementary strengths of vision and proprioception to develop a point-goal navigation system for legged robots, called VP-Nav. Legged systems are capable of traversing more complex terrain than wheeled robots, but to fully utilize this capability, we need a high-level path planner in the navigation system to be aware of the walking capabilities of the low-level locomotion policy in varying environments. We achieve this by using proprioceptive feedback to ensure the safety of the planned path by sensing unexpected obstacles like glass walls, terrain properties like slipperiness or softness of the ground and robot properties like extra payload that are likely missed by vision. The navigation system uses onboard cameras to generate an occupancy map and a corresponding cost map to reach the goal. A fast marching planner then generates a target path. A velocity command generator takes this as input to generate the desired velocity for the walking policy. A safety advisor module adds sensed unexpected obstacles to the occupancy map and environment-determined speed limits to the velocity command generator. We show superior performance compared to wheeled robot baselines, and ablation studies which have disjoint high-level planning and low-level control. We also show the real-world deployment of VP-Nav on a quadruped robot with onboard sensors and computation.
Deep Whole-Body Control: Learning a Unified Policy for Manipulation and Locomotion (CoRL 2022) Zipeng Fu 2022-09-19 | Project webpage: manipulation-locomotion.github.ioby Zipeng Fu, Xuxin Cheng and Deepak PathakAbstract: An attached arm can significantly increase the applicability of legged robots to several mobile manipulation tasks that are not possible for the wheeled or tracked counterparts. The standard control pipeline for such legged manipulators is to decouple the controller into that of manipulation and locomotion. However, this is ineffective and requires immense engineering to support coordination between the arm and legs, error can propagate across modules causing non-smooth unnatural motions. It is also biological implausible where there is evidence for strong motor synergies across limbs. In this work, we propose to learn a unified policy for whole-body control of a legged manipulator using reinforcement learning. We propose Regularized Online Adaptation to bridge the Sim2Real gap for high-DoF control, and Advantage Mixing exploiting the causal dependency in the action space to overcome local minima during training the whole-body system. We also present a simple design for a low-cost legged manipulator, and find that our unified policy can demonstrate dynamic and agile behaviors across several task setups.