Uploaded April 2026 | Updated September 2026, 2 weeks ago
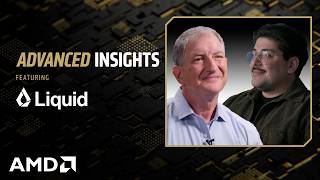
Mark Papermaster sits down with Liquid AI co-founder and CEO Ramin Hasani to explore how efficient, multimodal foundation models can bring AI beyond the cloud and onto real hardware at the edge. From proactive agents and hardware-in-the-loop optimization to lower latency, lower power, stronger privacy, and open ecosystems, this episode looks at what it will take to scale AI across PCs and other devices.
Key Takeaways
• Liquid Foundation Models are designed to bring powerful generative and agentic AI capabilities directly to PCs and other devices.
• Hardware-software co-design can reduce model size, latency, memory use and energy consumption without sacrificing performance.
• Efficient on-device AI can improve privacy, enable offline use and expand access to intelligence across billions of devices.
Chapters
00:00 Introducing Liquid AI and Ramin Hasani
00:33 Rethinking Where and How AI Runs
01:18 Building Efficient Foundation Models
02:25 From MIT Research to Liquid Neural Networks
03:08 Packing More Intelligence into Smaller Models
04:50 Moving Beyond Trillion-Parameter Cloud Models
06:04 Shrinking AI Without Sacrificing Quality
06:34 Exploring Alternatives to Transformer Architectures
07:54 Designing Models with Hardware in the Loop
09:04 Optimizing AI for CPUs, GPUs and NPUs
09:43 Bringing Foundation Models Directly to Devices
10:20 Proactive AI Agents on the PC
12:24 Running Powerful AI Privately and Offline
13:35 Why On-Device Agentic AI Is a Game Changer
14:14 Using NPUs for Sustained, Low-Power AI
15:02 An Army of Specialized Foundation Models
15:24 Improving Reliability Through Verification
16:42 Keeping Sensitive Data on the Device
17:21 Can Efficient AI Reduce Energy Demand?
18:01 Designing Foundation Models for Any Processor
18:40 Ultra-Low-Latency and Multimodal AI
20:23 The Societal Impact of More Efficient AI
20:38 Open Source, ROCm and the AI Ecosystem
21:19 Growing the Liquid AI Developer Community
23:09 Looking Ahead to the Future of On-Device AI
24:04 Bringing AI to Billions of Devices
24:49 Democratizing Access to Intelligence
25:26 Integrating Foundation Models with Hardware
27:08 Holistic Design and the AMD–Liquid AI Partnership
27:45 Building the Next Generation Together
28:14 Mark’s Key Takeaways
29:21 Closing and Where to Watch or Listen
***
Subscribe: bit.ly/Subscribe_to_AMD
Join the AMD Gaming Discord Server: discord.gg/amd-gaming
Visit the AMD Gaming Community Website: amdgaming.com
Like us on Facebook: bit.ly/AMD_on_Facebook
Follow us on Twitter: bit.ly/AMD_On_Twitter
Follow us on Twitch: Twitch.tv/AMD
Follow us on LinkedIn: bit.ly/AMD_on_Linkedin
Follow us on Instagram: bit.ly/AMD_on_Instagram
©2026 Advanced Micro Devices, Inc. AMD, the AMD Arrow Logo, and combinations thereof are trademarks of Advanced Micro Devices, Inc. in the United States and other jurisdictions. Other names are for informational purposes only and may be trademarks of their respective owners.
Mark Papermaster sits down with Liquid AI co-founder and CEO Ramin Hasani to explore how efficient, multimodal foundation models can bring AI beyond the cloud and onto real hardware at the edge. From proactive agents and hardware-in-the-loop optimization to lower latency, lower power, stronger privacy, and open ecosystems, this episode looks at what it will take to scale AI across PCs and other devices.
Key Takeaways
• Liquid Foundation Models are designed to bring powerful generative and agentic AI capabilities directly to PCs and other devices.
• Hardware-software co-design can reduce model size, latency, memory use and energy consumption without sacrificing performance.
• Efficient on-device AI can improve privacy, enable offline use and expand access to intelligence across billions of devices.
Chapters
00:00 Introducing Liquid AI and Ramin Hasani
00:33 Rethinking Where and How AI Runs
01:18 Building Efficient Foundation Models
02:25 From MIT Research to Liquid Neural Networks
03:08 Packing More Intelligence into Smaller Models
04:50 Moving Beyond Trillion-Parameter Cloud Models
06:04 Shrinking AI Without Sacrificing Quality
06:34 Exploring Alternatives to Transformer Architectures
07:54 Designing Models with Hardware in the Loop
09:04 Optimizing AI for CPUs, GPUs and NPUs
09:43 Bringing Foundation Models Directly to Devices
10:20 Proactive AI Agents on the PC
12:24 Running Powerful AI Privately and Offline
13:35 Why On-Device Agentic AI Is a Game Changer
14:14 Using NPUs for Sustained, Low-Power AI
15:02 An Army of Specialized Foundation Models
15:24 Improving Reliability Through Verification
16:42 Keeping Sensitive Data on the Device
17:21 Can Efficient AI Reduce Energy Demand?
18:01 Designing Foundation Models for Any Processor
18:40 Ultra-Low-Latency and Multimodal AI
20:23 The Societal Impact of More Efficient AI
20:38 Open Source, ROCm and the AI Ecosystem
21:19 Growing the Liquid AI Developer Community
23:09 Looking Ahead to the Future of On-Device AI
24:04 Bringing AI to Billions of Devices
24:49 Democratizing Access to Intelligence
25:26 Integrating Foundation Models with Hardware
27:08 Holistic Design and the AMD–Liquid AI Partnership
27:45 Building the Next Generation Together
28:14 Mark’s Key Takeaways
29:21 Closing and Where to Watch or Listen
***
Subscribe: bit.ly/Subscribe_to_AMD
Join the AMD Gaming Discord Server: discord.gg/amd-gaming
Visit the AMD Gaming Community Website: amdgaming.com
Like us on Facebook: bit.ly/AMD_on_Facebook
Follow us on Twitter: bit.ly/AMD_On_Twitter
Follow us on Twitch: Twitch.tv/AMD
Follow us on LinkedIn: bit.ly/AMD_on_Linkedin
Follow us on Instagram: bit.ly/AMD_on_Instagram
©2026 Advanced Micro Devices, Inc. AMD, the AMD Arrow Logo, and combinations thereof are trademarks of Advanced Micro Devices, Inc. in the United States and other jurisdictions. Other names are for informational purposes only and may be trademarks of their respective owners.