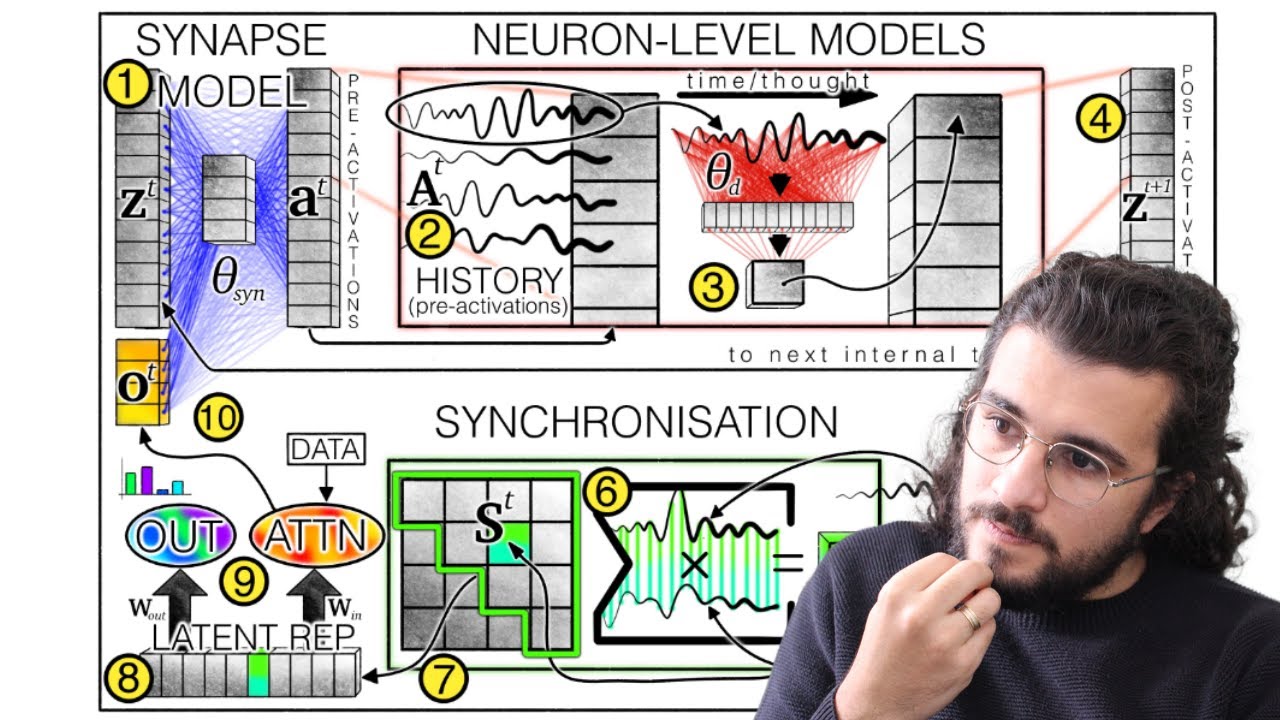
Continuous Thought Machine Deep Dive | Temporal Processing + Neural Synchronisation Deep Learning with Yacine 2025-07-24 | To try this awesome whiteboard:📌 [Free whiteboard] tldraw.com/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdid📌 [SDK to integrate into your app] https://tldraw.dev/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdidIn today's video, we're covering a novel neural dynamic architecture called continuous thought machines from Sakana.ai.The main architecture contribution the CTM bring is that the model now has a time dimension which works with what is called ticks.These ticks are decoupled from sequential information within the data.Table of Content:- Introduction: 0:00- Why neural models?: 4:16- interactive demo: 6:08- CTM architecture overview: 9:24- Pseudo-code overview: 18:59- method details walkthrough: 24:20- related architectures: 32:05- experiment imagenet: 34:20- experiment 2d maze: 39:04- experiment cifar10: 42:24- experiment cifar100: 45:15- experiment sorting: 47:39- experiment parity: 50:07- experiment mnist Q&A: 54:27- experiment reinforcement learning: 59:20- code notebook inference: 1:00:36- code architecture ctm: 1:02:51- next steps and discussion: 1:11:48- Interactive demo: pub.sakana.ai/ctm- paper: arxiv.org/abs/2505.05522----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
How to contribute to open source AI with ZERO experience | feat. DanAdvantage Deep Learning with Yacine 2025-12-04 | today I’m going to show you exactly how to get involved in open source the right way, using the popular reinforcement learning library PufferLib, with insights from one of its contributors, DanAdvantage. Which started with zero knowledge about RL!ALSO: learn to code from backend to full-stack to AI with Scrimba (extra 20% off pro with my link, great resource, I love the team):📌 full-stack course (great for beginners): scrimba.com/fullstack-path-c0fullstack?via=yacineMahdid 📌 AI Engineering course (my favorite): scrimba.com/the-ai-engineer-path-c02v?via=yacineMahdid📌 backend-engineering (new): scrimba.com/the-backend-developer-path-c0tbi0l98f?via=yacineMahdid # Table of Content- Intro: 0:00- Good mindset for open source contributions: 1:56- Use community as a driver for learning: 3:06- Become a power user to contribute: 4:40- DanAdvantage contribution story time: 5:55- Conclusion: 14:25## Shout Out- check out pufferlib and star the repo to support: github.com/PufferAI/PufferLib- check out danAdvantage: https://x.com/DanAdvantage- check out joseph tutorial: https://x.com/jsuarez5341/articlesEnjoy! 🌹----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:twitter: https://x.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Exploring Understanding R1-Zero-Like Training (Dr. GRPO) | Deep Learning Study Session Deep Learning with Yacine 2025-11-21 | November 20 session where we are diving into the paper "Understanding R1-Zero-Like Training: A Critical Perspective" by the Sea AI Lab which culminate in the Dr. GRPO algorithm.paper link 📌 arxiv.org/pdf/2503.20783come chat with me and ask any questions related to research deep learning in general! :) Enjoy! 🌹 If you want to continue the discussion holla at me on twitter:👋 https://x.com/yacinelearning
Exploring Understanding R1-Zero-Like Training (Dr. GRPO) | Deep Learning Study Session Deep Learning with Yacine 2025-11-20 | November 20 session where we are diving into the paper "Understanding R1-Zero-Like Training: A Critical Perspective" by the Sea AI Lab which culminate in the Dr. GRPO algorithm.paper link 📌 arxiv.org/pdf/2503.20783come chat with me and ask any questions related to research deep learning in general! :) Enjoy! 🌹 If you want to continue the discussion holla at me on twitter:👋 https://x.com/yacinelearning
How to build runescape for RL Agent? | Neural MMO v3 with Joseph Suarez Deep Learning with Yacine 2025-10-31 | October 29 session where we are going to go over the pufferlib 2.0 library and talk with Dr. Joseph Suarez on his intense work on the Neural MMO v3.0 environment👉 joseph suarez twitter: https://x.com/jsuarez5341👉 contribute to pufferlib over here: github.com/PufferAI/PufferLibpaper links :📌 PufferLib 2.0: Reinforcement Learning at 1M steps/s: openreview.net/pdf?id=qRyteMTgn0📌 about neural mmo: https://x.com/jsuarez5341/status/1866127102627438866come chat with the author and ask any questions related to RL and environment design:) Enjoy! 🌹 If you want to continue the discussion holla at me on twitter:👋 https://x.com/yacinelearning
How to Finetune 8 Billion Parameters with Evolution Strategies? | with Yulu Gan Deep Learning with Yacine 2025-10-24 | October 23 session where we have the pleasure of having a chat with Yulu Gan one of the author of the paper “Evolution Strategies at Scale: LLM Fine-Tuning Beyond Reinforcement Learning”👉 yulu gan twitter: https://x.com/yule_gan👉 his website: yulugan.com/about.html big thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering: 📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdid paper link 📌 arxiv.org/pdf/2509.24372 📌 previous discussion on the paper: youtube.com/live/LSmg6QCK69Ecome chat with the author and ask any questions related to research + evolutionary strategies! :) Enjoy! 🌹 If you want to continue the discussion holla at me on twitter:👋 https://x.com/yacinelearning
exploring Evolution Strategies at Scale for LLM Finetuning | Deep Learning Study Session Deep Learning with Yacine 2025-10-22 | october 21 session where we review the ES paper about finetuning LLM with billions of parameter!big thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering:📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdidpaper link📌 arxiv.org/pdf/2509.24372Come study with me and ask any questions related to deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
exploring TRM Less is More: Recursive Reasoning with Tiny Networks | Deep Learning Study Session Deep Learning with Yacine 2025-10-18 | october 17 session where we review the TRM paper yes more latent reasoning stuff!big thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering:📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdidpaper link📌 arxiv.org/pdf/2510.04871Come study with me and ask any questions related to deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
What are RLVR environments for LLMs? | Policy - Rollouts - Rubrics Deep Learning with Yacine 2025-10-15 | 🦋 check out prime intellect's envrionment hub to publish, explore and use RL environment: app.primeintellect.ai/dashboard/environments Reinforcement learning is becoming the defining ingredient behind the most capable AI agents. From OpenAI’s Deep Research to Anthropic’s Claude Code, RL is used to specialize models for reasoning, coding, and tool use.In this video we'll do a beginner friendly overview of Reinforcement Learning with Verifiable Rewards (RLVR) environment and how to build them using the verifiers library!📌 also, if you are a beginner: learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)# Table of Content00:00 - Introduction: RL’s growing role in agentic AI01:10 - The RLVR loop: dataset, policy, rollouts, rewards, updates02:13 - Overview of the state of RLVR03:50 - Small-model RLVR: performance, latency, and cost benefits06:00 - RLVR vs RLHF: key conceptual differences07:32 - Open-source frameworks: ReasoningGym, ART, TRL and Verifiers 08:12 - deep dive into the verifiers 7 steps with math-python env08:25 - deep dive into the verifiers | step 1 : data09:09 - deep dive into the verifiers | step 2 : interaction style09:40 - deep dive into the verifiers | step 3 : environment logic10:05 - deep dive into the verifiers | step 4 : rewards function (rubric)11:23 - deep dive into the verifiers | step 5 : parser (optional)11:46 - deep dive into the verifiers | step 6 : package environment12:07 - deep dive into the verifiers | step 7 : run eval or training12:30 - a few community environments13:25 - Case study: Building a Vision-Language RLVR environment feat alexine13:56 - vision SR1 - overview16:46 - vision SR1 - environment 118:29 - vision SR1 - environment 220:03 - Interview with prime Will Brown, creator of Verifiers20:18 - Interview with prime Will Brown - verifiers development story23:16 - Interview with prime Will Brown - what's the vision for environment hub?24:17 - Interview with prime Will Brown - what future is there for RL environment?26:27 - 👺🦋👺🦋👺🦋# Shout Out👺 big thanks for alexine for her envrionment and for hoping on the video, check her out folks: https://x.com/alexinexxx👺 thanks will for taking the time to have come down from gpu heaven to chat with us about verifiers: https://x.com/willccbbCommunity Environment:📌 MLE Bench Environment by C: app.primeintellect.ai/dashboard/environments/creetz/mle-bench📌 Ifeval-confusables by oso: app.primeintellect.ai/dashboard/environments/oso/ifeval-confusables📌 MAPP - Multi-Agent Path Planning Environment by salty duck: app.primeintellect.ai/dashboard/environments/salty-duck/mapp📌 Vision SR1 by ma gurl alexine: app.primeintellect.ai/dashboard/environments/primeintellect/vision-sr1Paper & Videos & Cool Links:📌 OpenAI’s Deep Research Team on Why Reinforcement Learning is the Future for AI Agents: youtube.com/watch?v=bNEvJYzoa8A📌 Reinforcement Learning Meets Large Language Models: A Survey of Advancements and Applications Across the LLM Lifecycle: arxiv.org/abs/2509.16679v1📌 Exploring Environments Hub: Your Language Model needs better (open) environments to learn: huggingface.co/blog/anakin87/environments-hub📌 How to Train Your Agent: Building Reliable Agents with RL — Kyle Corbitt, OpenPipe: youtube.com/watch?v=gEDl9C8s_-4📌 ProRL: Prolonged Reinforcement Learning Expands Reasoning Boundaries in Large Language Models: arxiv.org/abs/2505.24864v1📌 reasoning gym library: github.com/open-thought/reasoning-gym📌 ART library: github.com/OpenPipe/ART 📌 huggingface TRL: github.com/huggingface/trl 📌 verifiers library: github.com/PrimeIntellect-ai/verifiers ----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:twitter: https://x.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
exploring emergent hierarchical reasoning in LLMs with RL (2025) | Deep Learning Study Session Deep Learning with Yacine 2025-10-01 | September 30 session where we review the paper "exploring emergent hierarchical reasoning in LLMs with RL" yes we are going back to hierarchical reasoning!big thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering:📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdidpaper link📌 arxiv.org/abs/2509.03646Come study with me and ask any questions related to deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
adagrad, adadelta, adam, adamax, adamw, aaaahhhhhh | Deep Learning Study Session Deep Learning with Yacine 2025-09-20 | September 19 session, where we are going to study optimizers some more and untangle this big adamessbig thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering:📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdidfor the deepml problem set check them out here:📌 deep-ml.com/problemsin order of apparition:📌 magazine.sebastianraschka.com/p/the-big-llm-architecture-comparison?r=1w72fu&utm_medium=ios&triedRedirect=trueCome study with me and ask any questions related to deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
Optimizers, ARC-AGI and Evolutionary Algorithm | Deep Learning Study Session Deep Learning with Yacine 2025-09-17 | September 17 session, where we are going to study optimizers and also check a new result on arc-agi!big thanks to scrimba for sponsoring the live stream, get started here to learn full stack development + ai engineering:📌 scrimba.com/fullstack-path-c0fullstack?via=yacineMahdidin order of apparition:📌 arc-agi announcement: https://x.com/arcprize/status/1967998885701538060/photo/1📌 How I got the highest score on ARC-AGI again swapping Python for English: jeremyberman.substack.com/p/how-i-got-the-highest-score-on-arc-agi-again📌 How I came in first on ARC-AGI-Pub using Sonnet 3.5 with Evolutionary Test-time Compute: jeremyberman.substack.com/p/how-i-got-a-record-536-on-arc-agi📌 deep-ml.com/problems?ref=yacinelearningCome study with me and ask any questions related to deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
No BS Advices for Beginner Deep Learning Researchers Deep Learning with Yacine 2025-09-15 | 📌 learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)I found that surprisingly, a lot of students and engineers are interested in doing research.so here are 3 kinds of kinda blunt advice I gave recently in one of our paper review live streams.📌 also, if you are a beginner: learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)# Table of Content- Introduction: 0:00- following research passion with no career reward?: 1:34- why it's a good idea to follow that research passion?: 4:00- where to find research idea? : 6:23----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
No BS advice for deep learning beginners Deep Learning with Yacine 2025-09-04 | check out deep-ml here: https://www.deep-ml.com?ref=yacinelearningI receive a lot of DM from stressed-out students who want to get beginner guidance on the deep learning field.Often, people seeking this type of guidance are learning deep learning with the hope of achieving something else, which is not properly stated.So, here I’ll give two general guidelines to help you structure your goal-setting and your job trajectory.📌 also, if you are a beginner: learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)Table of Content:- Introduction: 0:00- beginner advice number 1: 2:01- beginner advice number 2: 5:46----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Learning the periodic table by heart in 2 days | deep learning study sessions Deep Learning with Yacine 2025-08-30 | This friday, we'll learn the full periodic table by heart and in order.buckle up folks we're going to learn about how memory work in the human mind and what that means for deep learning models.Don't hesitate to hop on to ask questions about anything machine learning or deep learning related!Shout out to all my members, really nice to hang out with you all!TLDRAW board is right here with the notes: tldraw.com/p/5Vb_r5X1u2-EeNeZ31rbo?d=v-3894.-4215.24909.12938.Xq-e5XMKtdPjwuPMRhSHF----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
Muon Optimizer for Dense Linear Layer Explained | Newton-Schulz + Momentum Deep Learning with Yacine 2025-08-18 | To try this awesome whiteboard:📌 [Free whiteboard] tldraw.com/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdid📌 [SDK to integrate into your app] https://tldraw.dev/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdidIn this tutorial, we will review the muon optimizer, which is currently making waves in large language modelling by powering Kimi K2.You will see it's not that complicated.📌 also, if you are a beginner: learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)# Table of Contents- introduction: 0:00- why muon is useful?: 2:04- adam overview: 3:30- adamw overview: 4:32- what muon is doing?: 7:31- muon authors overview: 8:26- muon results: 10:39- kimi k2 performance with muon-clip: 12:29- what does muon do?: 13:54- deep dive in newton schulz: 16:52- coding muon in numpy: 27:59test yourself here:📌 deep-ml.com/problems/172?ref=yacinelearningmore paper for deepdive:📌 overview: https://rixhabh.notion.site/Muon-2302d1eca8f6801c88e3f80e43c316da?pvs=74📌 Keller blog: kellerjordan.github.io/posts/muon📌 Jeremy blog: https://jeremybernste.in/writing/deriving-muon📌 newtonschulz overview: https://docs.modula.systems/algorithms/newton-schulz/📌 cool orthogonalization video: youtube.com/watch?v=vSczTbgc8Rc📌 if you liked the boat stuff haha: youtube.com/watch?v=zlFH3aC7Z_c&ab_channel=HowRidiculous----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
AdamW Optimizer from Scratch in Python Deep Learning with Yacine 2025-07-29 | To try this awesome whiteboard:📌 [Free whiteboard] tldraw.com/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdid📌 [SDK to integrate into your app] https://tldraw.dev/?utm_source=youtube&utm_medium=socials&utm_campaign=standard&utm_term=yacinemahdidIn this tutorial, we will review the AdamW optimizer, which is currently the state of the art in most deep learning training regimens.AdamW is a variant of Adam which apply regularization in the form of weight decay in a very specific way that makes it much more stable than the regular Adam optimizer.We'll break down where this regularization helps and how it differs from the traditional Adam + L2 regularization.📌 also, if you are a beginner: learn to code from full-stack to AI with Scrimba scrimba.com/?via=yacineMahdid (extra 20% off pro with my link, great resource, I love the team)# Table of Content- Introduction: 0:00- Where does AdamW fit?: 2:30- What type of regularization does AdamW apply?: 3:25- Why Adam with L2 sucked?: 4:49- Isn't L2 and Weight Decay the same?: 5:48- AdamW formula breakdown: 6:19- AdamW code implementation (lol): 14:32- AdamW Recap: 19:34 📌 [paper] Decoupled Weight Decay Regularization: arxiv.org/abs/1711.05101📌 [code] Implement AdamW Optimizer Step: deep-ml.com/problems/169?ref=yacinelearning----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Adam Optimizer from Scratch in Python Deep Learning with Yacine 2025-07-22 | In this tutorial, we will review the Adam optimizer, which is used during the training of deep neural networks.to code along check here:📌 deep-ml.com/problems/87?ref=yacinelearning# Table of Content- introduction: 0:00- theory: 0:35- formula walkthrough 1:48- numpy implementation: 10:28- success: 14:10 - there isnt much to it: 14:30----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Coding backprop through time in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-06-26 | We'll be going through some live coding exercises in Python, and I'll do my best to code the backdrop through time algo!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/62?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!Big thanks to all my sponsors, super fun hanging with you all!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
Coding a RNN in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-06-24 | We'll be going through some live coding exercises in Python, and I'll do my best to create a simple recurrent neural network!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/54?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!Big thanks to all my sponsors, super fun hanging with you all!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
What the heck is Artificial Immune System??? | AI Paper Review Deep Learning with Yacine 2025-06-16 | Buckle up folks, we are going to figure out what the heck the field of artificial immune system is and if it's still releveant in this day and age.I've discovered that field last week while trying to figure out what hypervector and hyperdimensional computing was while working on this deep-ml problem:📌 deep-ml.com/problems/74?ref=yacinelearningCheck out these resources if you re interested in diving deeper into HDC and AIS:📌 https://www.tu-chemnitz.de/etit/proaut/workshops_tutorials/vsa_ecai20/rsrc/vsa_slides.pdf📌 torchhd.readthedocs.io/en/stable/classification.html📌 quantamagazine.org/a-new-approach-to-computation-reimagines-artificial-intelligence-20230413/?mc_cid=ad9a93c472&mc_eid=506130a407Don't hesitate to hop on to ask questions about anything machine learning or deep learning related!Big thanks to all my sponsors, super fun hanging with you all!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
Coding a Composite Hypervector in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-06-09 | We'll be going through some live coding exercises in Python, and I'll do my best to create a composite hypervector for a dataset row!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/74?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!Big thanks to all my sponsors, super fun hanging with you all!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
Backpropagation with Automatic Differentiation from Scratch in Python Deep Learning with Yacine 2025-06-05 | In this tutorial, we will review the automatic differentiation algorithm which is at the core of the autograd library in Pytorch.# Table of Content- Introduction: 0:00- Automatic differentiation theory: 0:53- Computational graph definition: 3:30- Backpropagation with automatic differentiation: 7:04- Autograd from scratch in Python: 10:44- Autograd - addition: 13:52- Autograd - multiplication: 18:34- Autograd - ReLU: 20:44- Autograd - backward: 22:40- Recap: 26:13To follow along and try it yourself, you can head over here on deep-ml:📌 deep-ml.com/problems/26?ref=yacinelearningAlso, if you are interested in diving even deeper into Automatic Differentiation, do check out these two fantastic resources:📌 [Video] youtu.be/VMj-3S1tku0?si=Ce8Plk5qrisZjJNr📌 [Blog] mehta-rohan.com/writings/blog_posts/autodiff.html----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Coding Gaussian Elimination in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-06-03 | We'll be going through some live coding exercises in Python, and I'll do my best to implement the Gaussian Elimination for Solving Linear Systems!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/58?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!Big thanks to all my sponsors, really nice to hang out with you al!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
Masked Self-Attention from Scratch in Python Deep Learning with Yacine 2025-05-28 | In this tutorial, we will review the algorithm for the masked self-attention and code it in numpy.You can follow along here with the deep-ml problem set:📌 deep-ml.com/problems/107?ref=yacinelearning# Table of Content- Introduction: 0:00- Self-Attention Theory: 0:32- Algorithm Recipe: 2:18- Code Step 1 - Compute QKV: 7:26- Code Step 2 Compute attention scores: 9:18- Code Step 3 Applying Mask: 10:10- Code Step 4 Softmax Calculation: 10:37- Code Step 5 Computing the Output: 12:50- Conclusion: 13:27The algorithm is very commonly used in pretraining large language models, and being familiar with its quirks will allow you to better understand pre-training in LLMs.----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Reduced Row Echelon Form (RREF) Algorithm From Scratch in Python Deep Learning with Yacine 2025-05-20 | In this tutorial, we will review the algorithm for transforming an augmented matrix into its reduced row echelon form in Python.# Table of Content- Introduction: 0:00- Definition: 1:20- Algorithm Recipe: 4:10- Step 1 - Column iteration: 8:18- Step 2 - Selecting pivot row: 10:41- Step 3 - Scale pivot row: 16:27- Step 4 - Eliminate above and below: 17:51- Step 5 - Prepare for next iteration: 22:13- Recap: 23:16- Conclusion: 25:20If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/48?ref=yacinelearningand check out the theory in this book:📌 mml-book.github.io/book/mml-book.pdf----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Coding Reduced Row Echelon Form in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-05-18 | We'll be going through some live coding exercises in Python, and I'll do my best to implement the Reduced Row Echelon Form (RREF) function!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/48?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!Shout out to all my members, really nice to hang out with you all!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdid___Have a great week! 👋
How to train LLMs with long context? Deep Learning with Yacine 2025-05-09 | In today's video, I wanted to cover context windows in the transformer's architecture and how to make them BIG.# Table of Content- Introduction: 0:00- Why more context is good: 0:33- R1 longer context: 1:06- A little retrieval test: 1:56- Needle-in-a-haystack: 2:40- Multi-Round Needle-in-a-haystack: 3:38- Machine Translation from One Book MTOB: 4:52- Attention Calculation Recap: 6:16- How to encode positions: 8:51- Issue with increasing context: 10:07- How to extend context: 11:26- Fixing positional encoding: 11:45- Fixing Attention Calculation: 13:21- Flash Attention: 13:55- Sparse Attention: 14:52- Low-Rank Decomposition: 18:14- Chunking: 19:51- Other type of strategy using linear components: 21:44- LLama 4 changes: 24:12- Google Long Context Team (Nikolay Savinov): 25:33- see you folks! : 26:50This is an especially interesting topic, at least for me, to dig into because we are starting to see models with quite large context windows.For example, Gemini 2.5 has a context window of 1M tokens and Llama4 scout boasts 10M.Here are all the resources in this tutorial:📌 LLama 4 report on their 10M context window: ai.meta.com/blog/llama-4-multimodal-intelligence📌 Gemini 2.5 release note: https://blog.google/technology/google-deepmind/gemini-model-thinking-updates-march-2025/#gemini-2-5-thinking📌 Very solid review of transformers: synthesis.ai/2023/12/04/generative-ai-part-0-background-on-transformers📌 And another very solid review of long context: synthesis.ai/2024/04/08/lost-in-context-how-much-can-you-fit-into-a-transformer📌 How Rotary Position Embedding Supercharges Modern LLMs: youtube.com/watch?v=SMBkImDWOyQ&ab_channel=Jia-BinHuang📌 On The Computational Complexity of Self-Attention: arxiv.org/abs/2209.04881📌 Extending Context Window of Large Language Models via Positional Interpolation: arxiv.org/abs/2306.15595📌 Long-Context LLM Extension with Positional Encoding: youtube.com/watch?v=dc4chADushM&ab_channel=SashaRush📌 A Controlled Study on Long Context Extension and Generalization in LLMs: arxiv.org/abs/2409.12181📌 Flash Attention: arxiv.org/abs/2205.14135📌 Generating Long Sequences with Sparse Transformers: arxiv.org/pdf/1904.10509📌 Big Bird: Transformers for Longer Sequences: arxiv.org/abs/2007.14062📌 The Sparse Frontier: Sparse Attention Trade-offs in Transformer LLMs: arxiv.org/abs/2504.17768📌 Linformer: Self-Attention with Linear Complexity: arxiv.org/abs/2006.04768📌 Rethinking Attention with Performers: arxiv.org/abs/2009.14794📌 Transformer Quality in Linear Time: arxiv.org/abs/2202.10447📌 Various Lengths, Constant Speed: Efficient Language Modeling with LightningAttention: arxiv.org/pdf/2405.17381📌 MiniMax-01: Scaling Foundation Models with Lightning Attention: arxiv.org/abs/2501.08313📌 MEGABYTE: Modeling Million-byte Sequences withMultiscale Transformers: proceedings.neurips.cc/paper_files/paper/2023/file/f8f78f8043f35890181a824e53a57134-Paper-Conference.pdf📌 Leave No Context Behind: Efficient Infinite Context Transformers with Infini-attention: arxiv.org/abs/2404.07143📌 Titans: Learning to Memorize at Test Time: arxiv.org/abs/2501.00663📌 Efficiently Modeling Long Sequences with Structured State Spaces: arxiv.org/abs/2111.00396📌 Linear Attention and Mamba: New Power to Old Ideas: synthesis.ai/2024/11/20/linear-attention-and-mamba-new-power-to-old-ideas📌 Command A: An Enterprise-Ready Large Language Model: cohere.com/research/papers/command-a-technical-report.pdf📌 Scalable-Softmax Is Superior for Attention: arxiv.org/pdf/2501.19399----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Coding Gauss-Seidel Method in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-05-07 | We'll be going through some live coding exercises in Python, and I'll do my best to implement the Gauss-Seidel method for solving linear systems!If you want to code along, you can check the problem out over here:📌 deep-ml.com/problems/57?ref=yacinelearningDon't hesitate to hop on to ask questions about anything machine learning or deep learning related!----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacineaxyaGitHub: github.com/yacineMahdid___Have a great week! 👋
Coding Conjugate Gradient Method in Python | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-04-28 | We'll be going through some live coding exercises in Python, and I'll do my best to implement the conjugate gradient method for solving linear systems!If you want to code along you can check the problem out over here:📌 deep-ml.com/problems/63?ref=yacinelearning----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacineaxyaGitHub: github.com/yacineMahdid___Have a great week! 👋
What are Multi-Agent Systems in deep learning? | Theory Overview with MetaGPT Deep Learning with Yacine 2025-04-18 | Try out MGX from @metagptx tinyurl.com/2s3tmshmor check out their open-source project: github.com/geekan/MetaGPTMulti-Agent Systems sounds super cool, but you might be confused about what it is.In this tutorial, we will dive into the theory of two multi-agent system papers and a mini-project to showcase how these types of systems work:# Table of Content- Introduction: 0:00- Software Project Overview: 1:31- Theory of Multi-Agent Systems: 2:18- Overview of MetaGPT with Pong: 13:05- Building a Software Project: 19:16- Closing Words: 27:12- Bloopers: 27:49I had a blast working with that system. I don't know why but having these poor digital employees trying to figure out my vague requirements was absolutely hilarious!Here are more links for you to continue exploring:📌 MetaGPT: Meta Programming for A Multi-Agent Collaborative Framework: arxiv.org/abs/2308.00352📌 AFlow: Automating Agentic Workflow Generation: arxiv.org/abs/2410.10762📌 CAMEL-AI: camel-ai.org📌 Generative Agents: Interactive Simulacra of Human Behavior: arxiv.org/abs/2304.03442#MetaGPT #DeepWisdom #MGX ----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
How to learn AI Engineering? Deep Learning with Yacine 2025-04-09 | Start right over here! 📌 scrimba.com/the-ai-engineer-path-c02v?via=yacineMahdidAI Engineering is very different from other data-related skills. It's much closer to software engineering. In today's video, I'll show you my preferred resources for adding that skill to your toolbelt.# Table of Contents- Introduction: 0:00- Step 0 - Learn the tools: 1:13- Sneakpeek of Scrimba UI: 2:52- AI Engineering Path modules overview: 4:41- Step 1 - Expand skills through projects: 6:42- LLM's Engineering Handbook Project: 7:43- Step 2 - Learn foundational models in depth: 8:58- AI Engineering book by Chip: 9:24- Final words: 10:48The two books I recommend are these ones:📌LLM Engineer's Handbook: Master the art of engineering large language models from concept to production: amazon.ca/LLM-Engineers-Handbook-engineering-production/dp/1836200072📌 AI Engineering: Building Applications with Foundation Models : amazon.ca/AI-Engineering-Building-Applications-Foundation/dp/1098166302Here are a whole bunch of useful resources to supplement the above:📌 Chip Huyen blog post is a very neat resource, too: huyenchip.com/blog📌 LLM engineering handbook early draft: medium.com/decodingml/an-end-to-end-framework-for-production-ready-llm-systems-by-building-your-llm-twin-2cc6bb01141f📌 HuggingFace learn: huggingface.co/learn📌 There is also this beautiful book about LLM: Hands-On Large Language Models: Language Understanding and Generation (a bit more theoretical, though): amazon.ca/Hands-Large-Language-Models-Understanding/dp/1098150961📌 This nice visual blog about deep learning architecture, very well made: newsletter.maartengrootendorst.com/p/a-visual-guide-to-mixture-of-expertsDon't go too much into analysis paralysis; get started and learn!PS: Try to count how many times I'm saying "actually" lol.----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacinelearningGitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
How to Code Singular Value Decomposition? | Mathematics for Machine Learning Study Session Deep Learning with Yacine 2025-04-04 | We'll be going through some live coding exercises in Python, and I'll do my best to implement Singular Value Decomposition using the Jacobian method.If you want to code along you can check the problem out over here:📌 deep-ml.com/problems/12?ref=yacinelearning----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:Twitter: twitter.com/yacineaxyaGitHub: github.com/yacineMahdid___Have a great week! 👋
MiniMax-01 Theory | 1M Context + Lightning Attention + GPU Optimization Deep Learning with Yacine 2025-03-31 | Here's an overview of the new open source models from MiniMax (MIT), minimax-text-01, and minimax-vl-01.This new model leverage lightning attention (a type of linear attention) in order to remove the quadratic bottleneck on the traditional softmax attention in transformer models.I strongly recommend you read the report after this overview; lots of cool information in it:📌 Paper: arxiv.org/abs/2501.08313📌 Repo: github.com/MiniMax-AI/MiniMax-01📌 Chat Interface: chat.minimax.ioTable of contents:- Introduction: 0:00- Model Overview: 3:04- Main Result Overview: 8:14- Background Information on Linear Attention: 11:00- Lightning Attention Overview: 16:07- I/O Optimization: 22:20- Pre-training recipe: 25:10- Post-training recipe: 26:31- Full Results: 30:42- Vision Modality for MiniMax-VL-01: 37:24- Demo of MiniMax-text-01: 41:20- Final Words: 45:04Key Takeaways:- 456 billion parameters and a 4-million-token context window, made for tasks requiring long-context understanding.- The Lightning Attention mechanism makes MiniMax-01 faster and more memory-efficient than traditional transformers.- MiniMax 01 surpasses Llama 3.1 in various benchmarks and challenges Claude, while also matching Deepseek V3 in specific tests.Papers & helpful media:📌 Lightning Attention: arxiv.org/abs/2405.17381📌 Lightning Attention 2: arxiv.org/abs/2401.04658📌 Flash Attention: arxiv.org/abs/2205.14135📌 Flash Attention 2: arxiv.org/abs/2307.08691📌 Ring Attention Explained: youtube.com/watch?v=jTJcP8iyoOM&ab_channel=DiscoverAI📌 Another Linear Attention Model (Linformer): youtube.com/watch?v=-_2AF9Lhweo&ab_channel=YannicKilcher📌 Needle in a Haystack Method: youtube.com/watch?v=KwRRuiCCdmc&ab_channel=GregKamradt ----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Linear Algebra Study Session - Coding Session in Python | Mathematics for Deep Learning Deep Learning with Yacine 2025-03-28 | March 27 session: Linear Algebra Coding Exercises in Python📌 deep-ml.com/problems?ref=yacinelearningCome study with me and ask any questions related to machine or deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
Linear Algebra Study Session - Laplace Expansion in Python | Mathematics for Deep Learning Deep Learning with Yacine 2025-03-26 | March 25 session: Coding Laplace Expansion in Pythondeep-ml.com/problems/13?ref=yacinelearningCome study with me and ask any questions related to machine or deep learning! :)Enjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
Linear Algebra Study Session - Sarrus Rule and Laplace Expansion | Mathematics for Deep Learning Deep Learning with Yacine 2025-03-17 | This Sunday, we will continue our beginner study session on linear algebra topics with the determinant!Come study with me and ask any questions related to machine or deep learning! :)---We're in Chapter 4.1 of the book on mathematics for machine learning:📌 mml-book.github.io/book/mml-book.pdfHere are the four videos I greatly recommend watching to get a solid intuition on what the determinant actually is:📌 (Geometric intuition): youtube.com/watch?v=Ip3X9LOh2dk&ab_channel=3Blue1Brown📌 (Laplace Expansion): youtube.com/watch?v=cAARX18-74g&ab_channel=JeffreyChasnov📌 (Sarrus Rule): youtube.com/watch?v=4xFIi0JF2AM&ab_channel=KhanAcademy📌 (Geometric intuition for Gaussian Elimination): youtube.com/watch?v=2tlwSqblrvU&ab_channel=LeiosLabsEnjoy! 🌹Do consider hopping up into our Discord for more discussions:👉 discord.gg/QpkxRbQBpf
What is Prompt Chaining in AI Agents? - Theory and Code Deep Learning with Yacine 2025-03-14 | 👨💻 If you are new to AI, check out this course by Scrimba: scrimba.com/the-ai-engineer-path-c02v?via=yacineMahdidYou might have heard the term prompt chaining in the context of AI Engineering, and you might be wondering how to apply it.In this short workflow tutorial, we are going to check out the structure of this very simple technique with code examples.# Table of Contents- Introduction: 0:00- Prompt Chaining Overview: 0:36- Cost-benefit of Prompt Chaining: 1:54- Example Project with Prompt Chaining: 2:34- Single Prompt Version: 4:42- Long Prompt Chaining Version: 10:14- Short Prompt Chaining Version: 13:22- Jupyter Notebook Version: 14:52- Improvement with Backend Engineering: 17:43- Conclusion: 21:25Here are a few interesting resources:1. Rivet the open-source LLM diagram software I'm using: rivet.ironcladapp.com2. DataCamp article on prompt chaining (very good): datacamp.com/tutorial/prompt-chaining-llm3. Anthropic article on prompt chaining (super good): docs.anthropic.com/en/docs/build-with-claude/prompt-engineering/chain-prompts----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Introduction to AI Agents - Theory and Code Deep Learning with Yacine 2025-03-10 | 👨💻 If you are new to AI, check out this course by Scrimba: scrimba.com/the-ai-engineer-path-c02v?via=yacineMahdidYou might wonder what agents are and be a bit confused when you found no clear cut definition. In today’s tutorial, we’re going to clarify that with a bit of theory and several code walkthroughs.# Table of Contents- Introduction: 0:00- What is an Agent: 1:50- HuggingFace agents definitions overview: 4:01- Agent vs workflows: 8:20- Prompt Chaining: 10:25- Routing: 12:28- Parallelization: 16:03- Orchestrator-Workers: 18:13- Evaluator-Optimizer: 24:18- Why you shouldn't build autonomous agents: 29:47- Focus on simple agentic systems: 34:22HuggingFace Paper:📌 huggingface.co/papers/2502.02649Anthropic Blog post:📌 anthropic.com/engineering/building-effective-agentsAnthorpic Video: 📌 youtube.com/watch?v=LP5OCa20Zpg&ab_channel=Anthropic----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Dont work in LLMs. - Yan Lecun Meta #deeplearning #llm Deep Learning with Yacine 2025-03-04 | Still, LLMs are nice and should be improved.
Why I would still learn to program in 2025 (even with AI). Deep Learning with Yacine 2025-02-26 | 30 days free trial of Brilliant + 20% off premium subscription over here: brilliant.org/deeplearningwithyacineContrary to what Jensen, CEO of NVIDIA says, I still think you should learn to program in 2025. In this tutorial, I outline the three main reasons why I believe that:# Table of Content- Introduction: 0:00- Programming is not about coding: 0:58- What Francois Chollet thinks: 3:33- Programming concepts help with problem-solving: 4:27- Programming makes you better at using AI: 12:42- Conclusion: 15:14FTC disclaimer: This video was sponsored by Brilliant----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Machine learning sucks. - Yann Lecun Meta #deeplearning #llm Deep Learning with Yacine 2025-02-25 | Highlighting the shortcomings of LLM is important.
AGI by 2026? - Dario Amodei CEO Anthropic #deeplearning #llm #machinelearning Deep Learning with Yacine 2025-02-20 | AGI between 2026 and 2126 confirmed!
LLMs are conscious? - Geoffrey Hinton reaction #machinelearning #deeplearning #llm Deep Learning with Yacine 2025-02-18 | How many neurons do you need to remove before consciousness goes away? 🤪
KL Divergence in DeepSeek R1 | Implementation Walk-through Deep Learning with Yacine 2025-02-13 | Sometimes, you read a deep learning formula and you have no idea where it comes from.In this tutorial we are going to dive (too) deep into the KL divergence implementation of GRPO in DeepSeek R1.## Table of Content:- Introduction: 0:00- KL Divergence in GRPO vs PPO: 1:00- KL Divergence refresher: 2:30- Monte Carlo estimation of KL divergence: 6:42- Schulman blog: 7:58- k1 = log(q/p): 8:55- k2 = 0.5*log(p/q)^2: 11:23- k3 = (p/q - 1) - log(p/q): 13:35- benchmarking: 15:58- takeaways: 18:43Great tutorial by Serrano on KL Divergence over here:📌 youtu.be/sjgZxuCm_8Q?si=TYcxmXqWZm62JL0zAwesome blog post by Schulman:📌 http://joschu.net/blog/kl-approx.htmlEnjoy! 🌹----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
Group Relative Policy Optimization (GRPO) - Formula and Code Deep Learning with Yacine 2025-02-05 | The GRPO algorithm is at the heart of the newest DeepSeek R1 architecture. In this tutorial, we will discuss the details of the formula along with a code implementation walkthrough from the HuggingFace post-training team!# Table of Content- Introduction: 0:00- PPO vs GRPO: 1:18- PPO formula overview: 4:24- GRPO formula overview: 7:49- GRPO pseudo code: 11:11- GRPO Trainer code: 13:21- Conclusion: 23:48GRPO In HuggingFace: 📌 huggingface.co/docs/trl/main/en/grpo_trainerGRPO Trainer on Github:📌 github.com/huggingface/trl/blob/main/trl/trainer/grpo_trainer.py#L568DeepSeek Math paper:📌 arxiv.org/pdf/2402.03300Another cool walkthrough of GRPO:📌 youtube.com/watch?v=bAWV_yrqx4w&ab_channel=YannicKilcherAwesome PPO tutorial:📌 youtube.com/watch?v=TjHH_--7l8g&ab_channel=Serrano.AcademyEnjoy! 🌹----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
DeepSeek R1 Theory Overview | GRPO + RL + SFT Deep Learning with Yacine 2025-01-31 | Here's an overview of the DeepSeek R1 paper. I read the paper this week and I was fascinated by the methods, however it was a bit difficult to follow what was going on with all the models being used.I found a neat map of the methodology which I'll be using in this tutorial to walk you through the paper.I strongly recommend you to still read the paper over here:📌 PAPER: arxiv.org/pdf/2501.12948and also to check out these other two video for the GRPO bit:📌 youtube.com/watch?v=XMnxKGVnEUc&ab_channel=UmarJamil📌 youtube.com/watch?v=bAWV_yrqx4w&ab_channel=YannicKilcherbtw map I'm using is over here:reddit.com/r/LocalLLaMA/comments/1i66j4f/deepseekr1_training_pipeline_visualizedTable of content- Introduction: 0:00- DeepSeek R1-zero path: 2:23- Reinforcement learning setup: 3:59- Group Relative Policy Optimization (GRPO): 7:03- DeepSeek R1-zero result: 11:40- Cold start supervised fine-tuning: 15:30- Consistency reward for CoT: 16:19- Supervised Fine tuning data generation: 17:17- Reinforcement learning with neural reward model: 19:47- Distillation: 21:26- Conclusion: 24:34----Join the newsletter for weekly AI content: yacinemahdid.comJoin the Discord for general discussion: discord.gg/QpkxRbQBpf----Follow Me Online Here:GitHub: github.com/yacineMahdidLinkedIn: linkedin.com/in/yacinemahdid___Have a great week! 👋
What are Foundational Models in Deep Learning? #deeplearning #machinelearning #ai Deep Learning with Yacine 2025-01-30 | LxM are the way to go!
Great course for learning deep learning #deeplearning #programming Deep Learning with Yacine 2025-01-28 | 👉 course.fast.ai
Learning to program in 2025? - Jensen Huang NVIDIA CEO reaction #deeplearning #programming #ai Deep Learning with Yacine 2025-01-25 | ... Yeah no, learn to program folks.